PLC ENGINEERING

Blog

Home

Blog

  • Siemens ET 200M & IM 153 Engineering Reference Guide
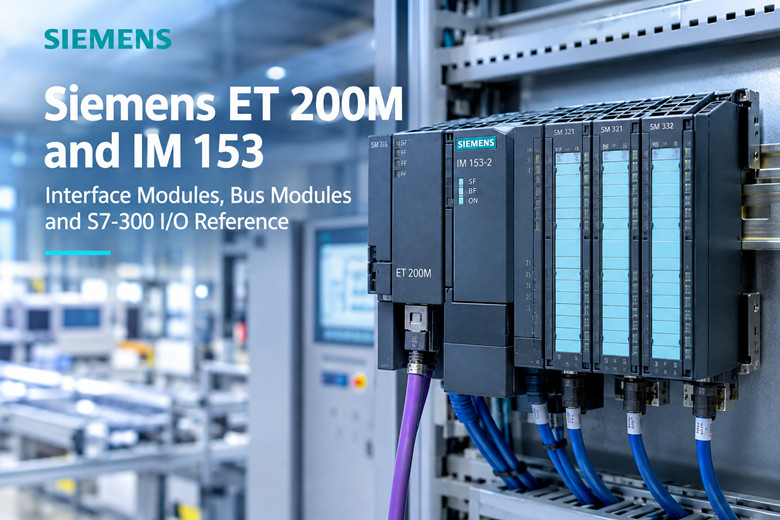
    Siemens ET 200M & IM 153 Engineering Reference Guide Sep 22, 2026
      System Architecture, Module Compatibility, Power Budgeting, and Diagnostics  1. Overview & System Architecture   The Siemens ET 200M is a modular distributed I/O station designed to mount standard S7-300 signal modules on an S7-300 profile rail (IP20 rating). It bridges field I/O back to a central programmable logic controller over a single bus link, substantially reducing panel wiring, terminal counts, and commissioning overhead. ET 200M stations contain no user logic or retentive process data; control remains strictly with the PLC CPU. An operational ET 200M station consists of five core hardware assemblies: · Profile Rail & Bus Modules: Active backplane bus modules (BM PS, BM IM, BM IM/IM) allow hot swapping without interrupting adjacent operational modules. · Interface Module (IM): IM 153-1, IM 153-2, IM 153-2 FO, or IM 153-4 PN managing communication, backplane power delivery, diagnostics, and redundancy. · Signal Modules (SM): Standard S7-300 digital and analog input/output modules (SM 321, SM 322, SM 323, SM 331, SM 332, SM 334, and fail-safe SM 336). · Function & Communication Processors (FM/CP): High-speed counter modules (FM 350-1), positioning modules (FM 351), and serial communication modules (CP 340/341). · Power Supply & Field Connectors: Optional PS 307 load power supplies (2A/5A), front connector blocks (20-pin / 40-pin), and bus shielding hardware.   2. Interface Module (IM 153) Selection   Interface modules establish the fieldbus network and define redundant capabilities: · IM 153-1 (PROFIBUS DP): Standard single-interface module supporting baud rates from 9.6 kbit/s up to 12 Mbit/s. Suitable for non-critical, non-redundant stations. DP node address is configured directly via on-module DIP switches. · IM 153-2 / IM 153-2 FO (PROFIBUS DP): High-feature interface supporting bumpless active redundancy when paired with an S7-400H redundant master. The fiber-optic (FO) version provides galvanic isolation across lightning-prone or high-EMI industrial runs. · IM 153-4 PN (PROFINET IO): Industrial Ethernet interface operating at 100 Mbit/s full-duplex. Features an integrated 2-port switch enabling daisy-chain line topologies without external network switches.   3. Power Budgeting & Mechanical Layout   A reliable ET 200M station requires careful calculation of two distinct electrical circuits before populating slots: · Backplane Current Budget: The IM supplies internal logic power across the backplane bus. Sum the backplane draw of all inserted SM/FM/CP modules and ensure the aggregate does not exceed the IM rated supply limit to avoid intermittent trip-outs. · 24 V DC Load Supply: Field sensors, actuator coils, and digital output transistors draw from an isolated external 24 V DC supply. Factor in a 25% to 30% margin over nominal current for inductive inrush. Verify voltage levels at the furthest end of the rail to prevent drop-induced channel dropouts. · Slot Capacity: A single rack accommodates up to 8 S7-300 I/O modules. Single-IM configurations consume slot 1; redundant architectures utilize a BM IM/IM spanning slots 1 and 2.   4. Hardware Configuration & Lifecycle Migration   · Engineering Environment: STEP 7 V5.x (HW Config) configures PROFIBUS DP and S7-400H setups. TIA Portal and GSDML device definitions manage IM 153-4 PN stations. Verify GSD/GSDML revision accuracy to ensure station connectivity. · Migration & Coexistence: For installations migrating toward S7-1500 controllers, existing ET 200M stations can either be integrated via IM 153-4 PN or bridged to PROFINET through DP/PN Couplers or IE/PB Links, preserving existing wiring and spare inventories. · Order Number (MLFB) Rigor: Always match the complete MLFB tail after the second hyphen (e.g., 6ES7 321-1BH02-0AA0 vs older variants) to guarantee exact diagnostic capabilities, isolation ratings, and interrupt response times.   5. Troubleshooting & Maintenance Guide   · IM Bus Fault (BF Solid / Flashing): Indicates duplicate node addresses, station absent from PLC hardware configuration, baud rate mismatch, unpowered end-of-line terminators, or reversed PROFIBUS A/B lines. Always inspect master slave diagnostics first. · Intermittent Faults on Drive Start: Noise induced on signal lines. Bond cable shields directly to cabinet ground bars using 360-degree shield clamps. Route communication cables in dedicated trays separate from VFD motor leads. · Individual Channel Failure: A healthy module with isolated dead outputs indicates external 24 V DC load voltage loss or thermal overload trip. For analog channels stuck at min/max limits, inspect sensor polarity, wire breaks, or common-mode ground loops. · Hot-Swap Procedure: Slide the front connector off the faulty module without disturbing field wiring. Disengage the mechanical latch, replace the module onto the active bus module, remount the front connector, and confirm LED recovery and diagnostic buffer clearance.    
  • Keeping an ABB Legacy Line Alive: What AC 800M, AC 500 and S800 I/O Users Should Keep on the Shelf
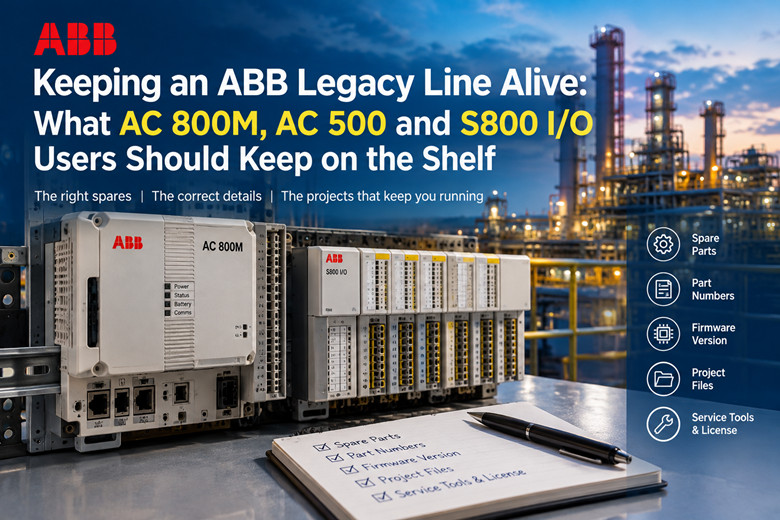
    Keeping an ABB Legacy Line Alive: What AC 800M, AC 500 and S800 I/O Users Should Keep on the Shelf Sep 17, 2026
      The call came in at 1:40 in the morning, which is when this kind of call always arrives. A water utility in a coastal region, one of several plants feeding the same distribution network, had lost a communication module on a night shift. The operator watching the board saw a station drop off the overview. A trend flatlined. The pump lineup that station was controlling stopped answering commands, and a reservoir level began a slow, patient climb toward a high-high alarm that nobody wanted to meet at four in the morning. The crew did everything right in the first twenty minutes. They cycled power on the rack. They reseated the fiber. They pulled diagnostics and found that the interface module had gone dark: no heartbeat, no backup controller to take over, because this station was a single configuration rather than a redundant pair. The technician on shift was competent. He knew exactly which module had failed. What he could not tell anybody at two in the morning was the part number of the replacement, the firmware revision it had to carry, and where the project file that matched this controller had gone. The failure itself was mundane. The recovery took eleven hours, and almost none of those hours were spent fixing hardware. This is a composite of calls I have watched play out more times than I can count, at utilities, at paper mills, at a cement plant that ran two shifts short while a spare sat in a warehouse three hundred kilometers away with the wrong suffix on the label. Nothing in the story is exotic. That is the point. The expensive part of an unplanned outage on an older ABB control system is rarely the broken part. It is the missing paperwork around the broken part.   What went wrong, hour by hour   Start with the module. The station ran a controller under an 800xA system, with S800 I/O out in the field and a communication interface tying the I/O station back to the controller over the CEX bus. The interface had failed. The plant had no spare on the shelf. It had been ordered once, years ago, as a project spare, and the spare had been consumed during a different incident and never replaced. That is the first quiet mistake, and it is the most common one: a spare that gets used and never restocked because nobody owns the restocking. The second mistake was in the records. The CMMS listed the module by a generic description and a part number that was close but not exact. When the night tech tried to raise a purchase order against it, the distributor came back asking which revision, which variant, whether it was the two-port version or the single-port version. Nobody on site could answer with confidence, because the nameplate was on the back of a module deep inside a marshalling cabinet and the maintenance window to go look was the same window they were trying to avoid. The third mistake was the firmware. Even once the right family was identified, the replacement had to carry a unit-software version compatible with the rest of the system. Controllers and interfaces in these families are not interchangeable across arbitrary revisions. A module with the wrong firmware does not simply drop in; it creates a new fault while you are still standing in the cabinet with a flashlight in your teeth. The fourth mistake was the project. The engineering project, the one that actually describes this controller's configuration, had last been edited by a contractor who had since moved on. The only known copy lived on his laptop. There was a backup somewhere, on a server nobody had logged into in a year, behind a password held by someone on annual leave. The plant could physically replace the module and still be unable to bring the line back, because a replacement controller needs a matching project revision before it will run the process. The fifth mistake was the media and licensing. The service tools, the license media, and the engineering workstation that could talk to the controller were scattered across three desks and one locked drawer. Nobody could find the media set quickly. Here is how the plant actually got running, and it is instructive because it was not heroic. They located the failed module's exact part number by pulling it and photographing the label. They confirmed the firmware revision from a commissioning note that, by luck, a retired engineer had kept. They recovered a project backup from the server, half an hour of anxious password hunting, and matched it against the controller's revision. Then they sourced a replacement interface from a specialist who held surplus stock. The replacement arrived by expedited freight late the next afternoon, was flashed to the correct unit software, and was online before the evening shift. The line was down for eleven hours. The module cost far less than the lost production. A shelf spare and a one-page record would have cut the outage to two hours. That is the whole lesson compressed into a night, and everything below is just the systematic version of it.   The pattern, once you strip the details away   Every one of these incidents reduces to the same five gaps. First, a module with no shelf spare. Second, a part number recorded wrong or recorded loosely in the maintenance system. Third, a firmware or unit-software version that nobody wrote down. Fourth, a project backup that exists only on a laptop that has left the building. Fifth, license media and service tools that cannot be found by the person who needs them at two in the morning. Each of those gaps is cheap to close in daylight. Each is ruinously expensive to discover during a shutdown. The engineering effort to walk a plant with a clipboard and a camera is measured in a few days of an engineer's time. The same discovery made under production pressure is measured in lost output, expedited freight, and the overtime of everybody standing around waiting. Notice also what did not cause the outage. It was not a mysterious firmware bug. It was not an obsolete protocol nobody supports. It was a known, catalogued, documented piece of industrial hardware from a vendor that still publishes replacement procedures for it. These systems were built to be maintained. The gap was on the plant's side of the fence.   The AC 800M controller family, and why the suffixes matter   The controller at the heart of that story belongs to the AC 800M family, which is the controller family used under ABB Ability System 800xA, and which also appears in older AC 500 installations that have been progressively modernized. Understanding the family matters because the model number on the label carries real engineering meaning, and the wrong suffix can mean a controller that cannot host the modules or the performance your station needs. PM851 is a 32-bit single-board computer that connects to S800 I/O directly over the ModuleBus and supports a maximum of one CEX bus module. That single-module limit is the detail that bites people who try to expand a PM851 station without checking first. If a station has grown a second communication need since commissioning, a PM851 is the wrong place to bolt it on. PM862 delivers roughly 1.2 times the performance of PM861 and supports up to twelve single or six redundant CEX bus modules. That is a meaningful jump in both throughput and expandability, and it is the workhorse answer for stations that need several interfaces. PM864 is about 50 percent faster than PM861 in executing an application program and supports up to twelve single CEX bus modules. Where a plant is pushing scan times or has a heavy application, the PM864 is the step that buyers ask about first. PM864A is the replacement for PM864 and supports twelve single or six redundant CEX modules, so it adds the redundant bus flexibility on top of the PM864 performance class. If you are standardizing shelf stock across a fleet, the A-suffix units are the ones to understand, because they are the forward path for a family that is otherwise aging. The PM865 and PM866 units extend the family for high-integrity and higher-performance duties. Those are the units you meet on safety-related and demanding control loops, and they are exactly the units where letting a spare run to zero is most costly, because the surrounding engineering is the least forgiving. The practical rule here is simple: record the exact model, including the suffix, for every controller you run. PM861, PM862, PM864 and PM864A are not interchangeable in the way the similar numbers suggest. The differences are in performance, in CEX bus capacity, and in where each sits on its replacement path. Buyers who need to source legacy AC 800M units and their matching accessories can start from the ABB range at ABB range and cross-check against the labels in their own cabinets.   Communication interfaces: the usual single point of failure   If the controller is the brain, the communication interfaces are the nerves, and the nerves are where most outages live. These CEX-bus modules are the common single point of failure because one interface can serve an entire I/O station. When that one interface dies, everything behind it goes blind at once. CI856 is the interface for S100 I/O, supporting up to five S100 I/O racks with up to 20 I/O boards each. That is a large span of process behind a single module, which is exactly why the CI856 belongs on any honest single-point-of-failure list. CI857 is the INSUM interface. Plants that run INSUM-based drive monitoring know it, and plants that have forgotten they have it get a reminder during their first unplanned event. CI858 drives ABB drives over the DDCS protocol, and it is upgraded with an external tool rather than a firmware download from the engineering tool. That last detail is not trivia. It is the difference between a spare that can be brought online in an hour and a spare that sits on the shelf being useless because the tool to prepare it was never tracked down. If you stock a CI858, you stock the way to program it too. CI865 is the ControlNet interface. It appears in plants that tied ABB control into a ControlNet segment, and it is one of the modules where supply is thinnest, so the case for shelf stock is strongest. CI867 and CI867A are Modbus TCP interfaces, and they are a good illustration of why the exact suffix matters. CI867 has two Ethernet ports, one full duplex at 100 Mbps and one half duplex at 10 Mbps. CI867A has a single full-duplex 100 Mbps port. A buyer who orders the wrong one gets a module that fits the slot and does not match the network design. A plant that keeps the wrong one on the shelf has a spare that is not a spare. Walk any legacy 800xA site and you will find that the controllers are usually the most documented items and the interfaces the least. That is backwards, because the interfaces fail first and take the most process down with them. Any plant that needs to fill gaps in its CEX-bus stock can compare notes with the industrial automation and PLC listings at PLC listings and industrial automation parts   S800 I/O in the field, down to the module and the terminal   Behind those interfaces sits the I/O, and on most of the installed base that means S800 I/O. Get specific here, because a vague I/O list is how plants end up ordering the wrong module during a shutdown. AI810 is an analog input module covering the 0(4)...20 mA and 0(2)...10 V ranges. It is the everyday analog workhorse, and it is also one of the first modules people run out of, because a single station can carry dozens of them. AI815 and AI820 round out the analog input story in different directions. AI820 is a differential analog input, used where the signal environment demands it. The AI830 family handles analog temperature inputs, which means thermocouples and resistance elements, and temperature loops are exactly the ones that quietly affect quality and safety while nobody is watching the trend. On the discrete side, DI810 is a digital input module and DO810 is a digital output module. These are the modules that fail in ones and twos during a bad electrical event, and they are cheap enough that there is no excuse for not holding a small buffer of each. Beyond the standard S800 line there is the S800L variant, which appears in installations where the physical form and density suit the cabinet better, and there are the SIL3-certified S800 High Integrity modules used in safety loops. You do not casually substitute a standard module into a safety loop, and you certainly do not leave a safety station without a certified spare. If a plant runs High Integrity I/O, that stock decision is not a cost decision, it is a compliance decision. One more item gets left off the asset list almost every time: the module termination units. These are the base units the I/O modules plug into, they carry the field wiring, and they age like everything else. A failed termination unit looks like a failed module until you have swapped both. Put them on the list, record their part numbers, and hold spares for the common types. This is all maintainable for a reason. ABB's own S800 I/O documentation includes module replacement procedures. That documentation exists because these modules are meant to be swapped in the field, by a competent technician, without scrapping the station. The design intent is on your side. The only thing standing between a plant and a two-hour recovery is whether the right module is on the shelf and whether anyone knows its exact identity.   The system context you need before ordering anything   Two facts about the broader system shape the way you plan spares. First, AC 800M is the controller family used under ABB Ability System 800xA, and it has been assessed against IEC 62443-4-1:2018 and IEC 62443-4-2:2018 secure development and component requirements. That matters for legacy users because it tells you the platform has a defined security posture with real process behind it. When you keep firmware and unit software current on the units you run, you are participating in that posture, not fighting it. Second, the supported I/O families across the installed base include Select I/O, S800, S800L, S900 and S100. A plant that has grown by acquisition or by phased upgrades can easily run three of those five in the same building. That is why a plant audit has to identify which I/O family each station actually runs before anything is ordered. The controller label tells you the controller. The I/O rack tells you the I/O family. They are not the same question, and assuming they are is how a perfectly good spare ends up in the wrong cabinet.   What to stock, station by station   Now translate all of that into shelf decisions. For every critical station, hold at least one spare controller of the exact model and suffix in use. If the station is a single configuration, that spare is not optional. If the station is a redundant pair, you have redundancy inside the running system but you still want a spare to restore redundancy, because a pair running on one healthy controller is one failure away from an outage. For every communication interface, hold one spare per critical interface type, and hold the tool and media needed to set it up. The CI858 case is the clearest example: a spare without the external upgrade tool is a paperweight. Count the CEX bus capacity of each controller while you are at it. If a PM851 station is already at its single-module limit, the spare strategy for that station has to account for the fact that you cannot simply add another interface during a crisis. For analog input modules, hold spares of the types that appear most often. AI810 is the volume module, so hold several. Add AI815, AI820 and the AI830 temperature family where those appear. For discrete, hold a small buffer of DI810 and DO810. For S800L and the SIL3-certified High Integrity modules, hold exactly the certified replacements the safety case requires, and log their certification status. For termination units, hold spares matched to your common module types. For the engineering project, hold an offline, retrievable archive with the revision that matches each controller, and store that archive somewhere that does not walk out of the building when a contractor leaves. That is the whole stocking philosophy in one sentence: match the spare to the label, and match the record to the spare.   The audit checklist, in the order you should walk it   This is the part that turns the night-shift story into a Monday-morning task. Work through it once, in daylight, and you will never rebuild your own version of that eleven-hour outage. Walk the plant and list every controller unit, every CEX bus module, every I/O module and every termination unit by part number and revision. Photograph the labels. Do not transcribe from memory and do not trust the CMMS until it agrees with the nameplate. Flag every single point of failure. Any interface that carries an entire station gets a flag. Any single controller with no redundant partner gets a flag. Any station that is one module deep between the process and the controller gets a flag. The PM851's single CEX bus limit is one such flag; a lone CI856 or CI867 serving a whole I/O station is another. Record firmware and unit-software versions next to each item. This is the record that saves you at two in the morning, because it is the one thing a distributor will ask and the one thing nobody wrote down. Separate what is still in production from what is repair-only or available only as surplus. Some modules you can still buy new. Some you can only repair or source from surplus stock. Knowing which is which tells you where to hold stock and where to accept lead-time risk. Make sure the engineering project and its backups are retrievable offline, stored with the version that matches each controller. An archive that requires a working network and a working laptop at the moment of failure is not a backup. It is a hope. Confirm that whoever holds the license media and the service tools is reachable, and that the media is stored somewhere known. Nobody should be hunting a locked drawer while a line is down. Store spares properly. Anti-static packaging, temperature-controlled storage, and the firmware media that updates each unit kept alongside it. A spare controller stored cheaply in a hot cabinet is a spare that fails on installation.   The money argument, without the sermon   Here is the reasoning, kept honest and grounded. The numbers move plant to plant, so treat what follows as an example of the shape of the comparison rather than a claim about your site. On one side, the carrying cost of a shelf spare is a one-time purchase plus a small storage and record-keeping overhead. For a single critical station, that is one controller, one or two interfaces, a handful of I/O modules, and the engineering record that ties them together. On the other side, the cost of an unplanned outage is lost production times the duration, plus expedited freight at a premium, plus the overtime of everyone involved, plus the risk of a secondary failure caused by a rushed restart. The asymmetry is the whole argument. A shelf spare is bought at list price in a calm market. The same module, sourced urgently during an outage, comes at expedited freight and possibly a marked-up surplus price, if it is available at all on the timeline you need. And the downtime cost dwarfs both. In most process plants, a few hours of lost output at a single station costs more than a sensible spare kit for that station costs to build and hold. The weaker but still real argument is the labor one. A shelf audit done in daylight costs engineering hours. The same discovery made at two in the morning costs production hours, because it happens while the plant is not making anything. You are choosing which currency to spend, and the daylight currency is cheaper by a wide margin. None of this requires a large capital program. It requires a few days of walking, a camera, a spreadsheet, and the discipline to replace a spare when you use one. The plants that recover in two hours are not the ones with the biggest budgets. They are the ones that know what is in their cabinets and what is on their shelves, down to the suffix.   The shelf, item by item   Item class | Example units | Why keep one Controller unit | PM851, PM861, PM862, PM864, PM864A, PM865, PM866 | The controller is the station. Without a matching spare, a single failure stops the process and the replacement needs the right firmware and project revision before it will run. Hold the exact model and suffix in use, and remember the PM851's single CEX bus limit. Communication interface | CI856, CI857, CI858, CI865, CI867, CI867A | One interface can carry a whole I/O station, so these are the usual single point of failure. Match the suffix carefully, since CI867A is not the same animal as CI867, and hold the tool and media that prepare the module, especially for the CI858. Analog input module | AI810, AI815, AI820, AI830 family | Analog inputs are the highest-volume modules on most stations and the ones you run out of first. Temperature inputs in particular sit on loops that quietly affect quality and safety. Analog output module | Analog output units in the S800 range | Outputs drive valves, positioners and final elements. A failed output channel can hold a final element in the wrong position, which is often worse than losing a reading. Digital input module | DI810 | Discrete inputs carry interlocks, status and permissives. They fail in ones and twos during electrical events, so a small buffer is cheap insurance. Digital output module | DO810 | Discrete outputs command pumps, solenoids and contactors. During a rushed restart, a failed output is the module most likely to be improvised around, which is exactly when you want a proper spare. Termination unit | Module termination units for the S800 types in use | The base units carry the field wiring and age like everything else. A failed termination unit looks like a failed module until you have swapped both, so keep the common types on the shelf. Engineering project archive | Offline project backup with the matching revision per controller | A replacement controller still needs a matching project revision before it will run the process. An archive that needs a working network at the moment of failure is not a backup. Where a legacy fleet actually gets its resilience Older ABB installations do not fail because they are old. They fail on the same mundane inventory and documentation gaps that any control system fails on, and they recover fast or slow depending on whether those gaps were closed in advance. The components are still documented, the replacement procedures still exist, and the modules still come out of the cabinet with a competent technician and the right replacement in hand. The story that opened this piece ended before the evening shift because somebody, eventually, found the part number, the firmware note and the project backup. Someone with a spare on the shelf and a one-page record would have ended it in two hours instead of eleven. That is the entire difference between a bad night and a routine one. The work to get there is unglamorous, and it is done in daylight, with a checklist, one cabinet at a time. -------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).  
  • PowerFlex 4, 40 and 70 Drives: Fault Codes, Common Failures, and the Spares That Keep Them Running
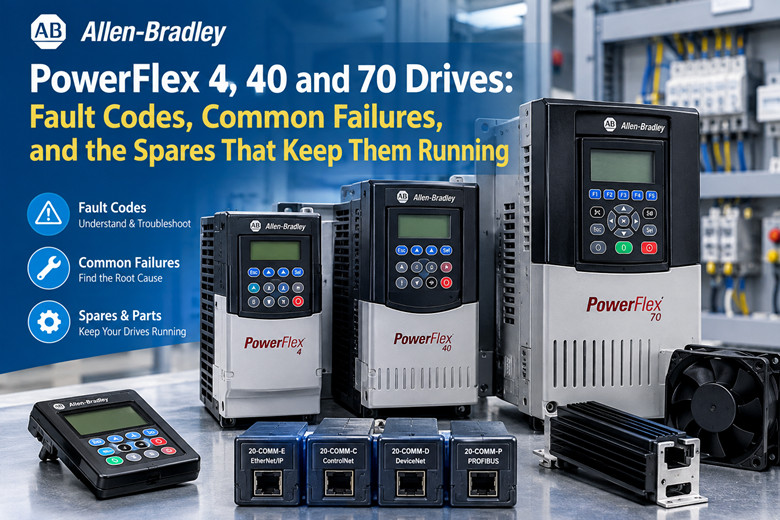
    PowerFlex 4, 40 and 70 Drives: Fault Codes, Common Failures, and the Spares That Keep Them Running Sep 16, 2026
      Catalog structure   Read the full catalog string before ordering anything. The prefix gives the family. The remainder gives frame, voltage class, rating and enclosure. 22A = PowerFlex 4. 22B = PowerFlex 40. 22F = PowerFlex 4M. 20A = PowerFlex 70. 20AD = PowerFlex 70. 20AE = PowerFlex 70. Communication adapters carry the 20-COMM prefix. 20-COMM-E for EtherNet/IP. 20-COMM-C for ControlNet. 20-COMM-D for DeviceNet. 20-COMM-P for PROFIBUS. Keypads: 22-HIM-A3 and 22-HIM-C2S. Braking resistors: 20-DR series. Spare parts for these drives sit under those prefixes only. If a seller quotes you a number that will not cross to one of the prefixes above, stop and verify it. The family prefix is the anchor. Everything downstream depends on it. Cross-check the frame. A 22B frame C is not a 22B frame A. Same family, different heatsink, different fan, different mounting, different power stage. The frame decides the fan, the heatsink, the terminal spacing and the board layout. Order by frame, not by family alone. A generic "PowerFlex 40 fan" does not exist. It is a PowerFlex 40 frame-specific fan, and the part number changes with the frame letter. Legacy stock moves through surplus channels. Numbers get misquoted. Confirm the full string on the drive label against the vendor listing before payment. See the Allen-Bradley range at Allen-Bradley range when you need to match a prefix to a stocked unit.   Electrical classes   Voltage classes appear in the catalog string. Read them there, not from memory. 240 V single-phase. 240 V three-phase. 400 V three-phase. 480 V three-phase. Power rating bands, stated generally: PowerFlex 4 covers roughly the 0.2 to 2.2 kW band. Frame dependent. PowerFlex 40 covers roughly the 0.4 to 11 kW band. Frame dependent. PowerFlex 70 extends higher. Frame dependent. These bands are orientation only. Exact kW and HP per frame must be read from the drive's own catalog string and the manual for that frame. Do not size a replacement from the band. Size it from the label. A published rating table here would be wrong for someone. Frame letters cover multiple ratings across voltage classes, and single-phase and three-phase versions of the same frame do not carry the same kW. The label is the only source that cannot mislead you. Practically: photograph the label. Note the full catalog string, the input voltage, the output kW or HP, the output current and the enclosure. That photograph is your order form. If the label is gone, and the machine still runs, you have a problem. Then you trace the motor nameplate FLA and the motor voltage, measure the running current, and pick a frame that covers the FLA with margin. That is the fallback path, not the preferred one. Single-phase input classes appear on the smaller frames. Three-phase classes dominate above the small band. Do not assume a drive that runs on 240 V three-phase will accept 240 V single-phase. Check the class in the string.   Interfaces   PowerFlex 4 and PowerFlex 40 expose a DSI (Drive Serial Interface) RS-485 port. PowerFlex 70 uses DPI and 20-COMM adapters for networking. The DSI port on the 4 and 40 carries serial communication and keypad traffic. Simple, two-wire, and easy to miswire. The 20-COMM adapters on the 70 slide into the drive and give it a network face: EtherNet/IP, ControlNet, DeviceNet or PROFIBUS. Keypads are removable. A keypad from a PowerFlex 4 moves to another PowerFlex 4 in the same family. Same for the 40 and same for the 70. This is the fastest diagnostic swap you have. Move a known-good keypad onto a dead-display drive and see if the display comes back. If the display comes back with the swapped keypad, the fault is in the keypad or its contacts. If the display stays dark with a known-good keypad, the fault is in the drive, and the control supply is the first suspect. A keypad is a terminal, not a permanent fixture. Treat it as a serviceable part and carry one. One 22-HIM-A3 or 22-HIM-C2S on the shelf covers an entire family.   Fault table   Faults latch. These drives do not self-clear. After the cause is corrected, the drive needs an explicit reset. Reset methods: keypad Stop/Reset key, a digital input programmed to fault reset, or a power cycle. Pick one and use it consistently so the next person knows the sequence. Fault | Meaning | First checks F004 | Undervoltage | Input voltage balance, loose line or motor terminations, weak bus capacitors under load F005 | Overvoltage | Deceleration time against load inertia, regeneration from the load, braking resistor fitted F007 | Motor Overload | Motor FLA setting against nameplate, mechanical binding, motor temperature F008 | Heatsink Overtemperature | Blocked or dirty heatsink fins, cooling fan operation, ambient temperature F013 | Ground Fault | Motor insulation, cable damage, moisture in the motor terminal box   F004 Undervoltage   A DC bus undervoltage trip. The bus fell below the level the drive needs to keep the output stable. First suspect: input voltage. Measure all three phases under load, not at rest. A sag that only shows when the machine runs is the one that matters. Second suspect: loose terminations. Line side and motor side. A high-resistance joint drops voltage under current. Tighten, inspect for heat discoloration, replace any lug that looks cooked. Third suspect: weak bus capacitors. The bus sags under load but holds at light load. This is an age fault, not a wiring fault. See the age section. Record the code history. If F004 appears only on high-load cycles, the input or the motor circuit is loading the bus beyond what the supply can hold.   F005 Overvoltage   A DC bus overvoltage trip. The bus rose above the level the drive tolerates. First suspect: deceleration time against load inertia. A high-inertia load pushed to stop too fast dumps energy back into the bus. Lengthen the deceleration ramp until the trip stops. Second suspect: regeneration from the load. An overhauling load or a driven load that goes faster than command pushes energy back. Gravity loads on hoists and conveyors do this. Third suspect: no braking resistor fitted. If the application regenerates, a 20-DR series braking resistor is the fix. Without one, the bus has nowhere to dump the energy. Check whether the drive had a braking resistor option and whether it is still connected. A disconnected or failed braking resistor turns a normal decel into an overvoltage trip. F007 Motor Overload A motor overload. The drive believes the motor is drawing beyond its thermal rating. First check: the motor FLA setting against the motor nameplate. A wrong FLA is the most common cause. Someone swaps a motor and leaves the old FLA in the drive. Second check: mechanical binding. A seized bearing, a jammed conveyor, a plugged pump. The motor draws more because the load draws more. Third check: motor temperature. Feel the frame, check the winding, confirm the motor's own cooling is working. A motor with a dead fan runs hot and trips the overload. Do not raise the FLA to stop the trip unless the nameplate justifies it. That masks the fault and cooks the motor.   F008 Heatsink Overtemperature   A heatsink overtemperature. The power stage is running hot. First check: blocked or dirty heatsink fins. Dust, lint, paper fibers, oil mist. Any coating on the fins insulates them and stops heat transfer. Second check: cooling fan operation. The fan should run whenever the drive is powered on many frames, and on demand on others. A fan that has stopped or slowed is the front end of most F008 events. Third check: ambient temperature. A drive in a closed cabinet, or a cabinet with a failed exhaust, sees high ambient and trips even with clean fins. F008 is a warning shot. Catch it early and replace the fan. Ignore it and the next event is a power stage failure.   F013 Ground Fault   A ground fault. Current is leaking from the output to ground. First check: motor insulation. A megger on the motor leads, motor disconnected from the drive. Second check: cable damage. Look at the run for pinches, chafing, water intrusion and rodent damage. Third check: moisture in the motor terminal box. Condensation, washdown spray, a loose gland. Water in the terminal box produces a ground fault that comes and goes with the weather. Disconnect the motor before you condemn the drive. A drive that trips F013 with the motor leads disconnected has an internal fault. A drive that trips only with the leads connected has a cable or motor fault.   Fault handling notes   These codes latch. The drive holds the fault until someone resets it. Clearing the symptom without correcting the cause just brings the fault back. Reset paths: keypad Stop/Reset. A digital input programmed to fault reset. A power cycle. Power cycle is the slowest and the least informative. Prefer a programmed reset input so the machine can be cleared from the control system. Record every fault. The order and the frequency matter. One F008 a year is a filter cleaning reminder. Three F008 in a week is a fan. F004 and F005 together point at a mechanical or connection fault, not the drive. Read the pair, not the single code. F007 and F013 together point at the motor and its cable. Check the motor before the drive. F008 alone, after a long clean run, points at the fan, the filter or the cabinet exhaust. Check airflow first. The fault code is the start of the diagnosis, not the answer. The cause sits in the input supply, the motor circuit, the mechanics or the environment, and the code only tells you which direction to look.   Two faults in sequence: F004 then F005   A loose motor terminal or a failing mechanical coupling can produce F004, then F005 seconds later. The sequence: The connection is loose. Current rises. Voltage at the terminal sags. The bus dips. F004 trips first. Then the connection re-makes, or the load breaks free and the motor suddenly unloads. The current collapses. The bus sees the load release as a voltage spike, or the mechanical shock sends the inertia back through the drive. F005 trips on the rebound. F004 followed by F005 within a short window is a mechanical or connection symptom. It is not a drive fault. Do not replace the drive on this pattern. Re-torque the motor terminals. Inspect the coupling, the belt, the gearbox, the keyway. Check the driven machine for a bind that releases. If you replace a drive on this signature, the new drive does the same thing. Same mechanical fault, same pair of codes. Treat the pair as a single event with two faces: a sag and a spike. Find the mechanical cause and both codes stop.   Failure points by age   Legacy drives fail in a predictable order. Age, not hours on the clock, drives most of it. DC bus electrolytic capacitors The electrolytic capacitors on the DC bus dry out. Their capacitance drops. Equivalent series resistance rises. The drive runs fine at light load. Under load the bus sags and the drive trips undervoltage, F004. Load it again and it trips again. This is the classic end-of-life signature. A drive that trips F004 only under load, with clean input and tight terminations, points at the bus capacitors.   Cooling fans   The fan is the number one consumable in these drives. It runs whenever the drive runs. Bearings dry out, the fan slows, then it stops. A stopped fan leads to F008 heatsink overtemperature. Run through F008 long enough and the power stage cooks. The fan is a fraction of the cost of a drive. Replace the fan on a schedule, or at the first sign of noise or slowing. Fan and heatsink part numbers are frame dependent. Match the frame.   IGBT and rectifier failures   Line transients and lightning events take out the input rectifier and the output IGBTs. A surge gets past the input protection and punches through a semiconductor junction. The drive goes dead. No display, or a display that shows a hard fault it will not clear. A power stage failure is usually a send-in-for-repair or replace event, not a field fix. Where the site sees lightning, the input protection is not cosmetic. It is what stands between a storm and a drive.   Control board switch-mode supply   The switch-mode supply on the control board dies. The display goes blank. The drive looks completely dead. Before you condemn the drive, check the control supply. A blank display has more than one cause, and a failed control supply is a board-level repair, not a power-stage repair. A known-good keypad swap tells you whether the display itself is the problem. If the display stays dark with a good keypad, the control supply is the next suspect.   Keypad contacts and the DSI / RJ-style port   The keypad contacts and the DSI or RJ-style port corrode. In humid or washdown areas the contacts oxidize and the connection goes intermittent. Symptom: intermittent no-communication faults. The drive runs, then the keypad drops out, then it comes back. Or the network drops the drive on the DSI port. Clean the contacts, inspect the port for corrosion or a bent pin, and swap in a known-good keypad. If the fault follows the keypad, replace the keypad. If it stays with the drive, the port or its board is the fault.   Conductive dust and washdown moisture   Conductive dust and washdown moisture cause ground and overcurrent faults. Metal dust, carbon dust, salty air and spray all lower the insulation resistance across terminals and boards. Ground faults, F013, and overcurrent trips follow. The drive may run dry and fail wet. It may run clean and fail after a washdown. Seal the enclosure. Route the washdown away from the drive. Clean with dry methods where possible. A wet drive that was fine yesterday and grounds today is telling you where the water went.   Frame dependent parts   Fan and heatsink part numbers are frame dependent. Order by frame letter. There is no universal fan for a family. Keep the frame letter on the spares tag. A shelf full of unlabeled fans is a shelf full of wrong parts.   Diagnostics without a laptop   You do not need a laptop or a network tool to find most faults. Six steps, in order. 1. Read the display and record the fault code history. Write down every code and the order they appeared. The sequence matters more than any single code. 2. Measure the three-phase input for balance and sag. Check all three phases at rest and under load. A phase that sags only under load is a real fault. 3. Measure the DC bus during a loaded run. Watch the bus while the machine works. A bus that sags under load points at capacitors or input supply, not at the motor. 4. Check motor insulation resistance before blaming the drive. Disconnect the motor. Megger the leads. A grounded or damp motor trips a healthy drive. 5. Confirm the acceleration and deceleration times against the load. Times that were right for the old machine may be wrong for the rebuilt one. Load inertia changes over the life of a machine. 6. Check the drive's ambient temperature and airflow path. Cabinet temperature, filter condition, fan operation, clearances. Heat is behind a large share of nuisance trips. These six steps catch the majority of field faults before you open a manual. Record what you measure so the next technician starts where you stopped. Field note: measure at the drive terminals, not at the panel. A healthy voltage at the panel and a sag at the drive terminals tells you the fault is in the run between them. Field note: check the motor FLA setting before any current diagnosis. A wrong FLA makes a healthy motor look like a fault. Field note: compare the trip against the machine cycle. A fault that lands at the same point every cycle is mechanical. A fault that lands at random is electrical or environmental. Field note: if the drive ran for years and now trips, suspect age parts before settings. Nobody changed the parameters last week. The capacitors and the fan did change. Spare VFDs for these checks and swaps are listed at industrial automation parts   Repair, swap or surplus   Three routes. Repair, replace, or surplus of the same number. Each has a place. Repair makes sense on larger frames and where boards are still available. A large frame drive with a failed board or fan is often worth repairing. The frame value is high, the mechanical parts are simple, and the repair keeps the existing parameter set and wiring in place. Replace with a newer PowerFlex 525, 527 or 750 when the frame is small, the drive is fully obsolete, and the application is standard. Newer drives give you current firmware, current network options and a support path. For a small frame doing a simple job, replacement is usually the better value. Surplus of the same catalog number is a legitimate route for keeping an old machine alive. A used drive of the exact catalog number drops in. Same mounting, same terminations, same parameter structure, same wiring. No re-engineering. The practical trap: a replacement drive needs the parameter set from the old one. Different catalog number, different parameter structure, different setup. Record the parameter list by hand, or save it with the vendor's own configuration software, before the old drive dies. A parameter list written down on paper is worth more than a drive in a box when the machine is down. Save from the drive while it still communicates. If the old drive is already dead, you reconstruct the list from the machine's requirements and the motor nameplate. That takes time you may not have. Keep the recorded parameter list with the machine. Tape a copy inside the cabinet. When a drive is swapped at 2 a.m., the list on the cabinet door is the difference between fifteen minutes and a shift.   Spares checklist   The shelf that keeps a legacy PowerFlex machine running. Part family | Catalog prefix | Why one should be on the shelf Keypad | 22-HIM-A3, 22-HIM-C2S | Fastest display and communication swap; covers a whole family Communication adapter | 20-COMM (E, C, D, P) | Network failure takes the drive offline; swap restores comms in minutes Braking resistor | 20-DR series | Missing or failed resistor turns normal decel into an F005 overvoltage trip Cooling fan | Frame dependent | Number one consumable; a dead fan leads to F008 then to power stage failure Spare drive, same frame | 22A, 22B, 22F, 20A | Drops in with the same mounting, wiring and parameter structure Spare drive, same catalog number | Same prefix as the failed unit | Direct swap; avoids re-engineering a replacement with a different structure Tag every spare with the frame letter and the full catalog string. An untagged fan is a wrong part. Store the recorded parameter list with the spare drive. A drive without its parameter set is a doorstop on the day you need it. The rule is simple. Match the prefix, match the frame, match the voltage class, and carry the recorded parameters. See the full industrial automation range at industrial automation range for the surrounding spares these machines need. ------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).      
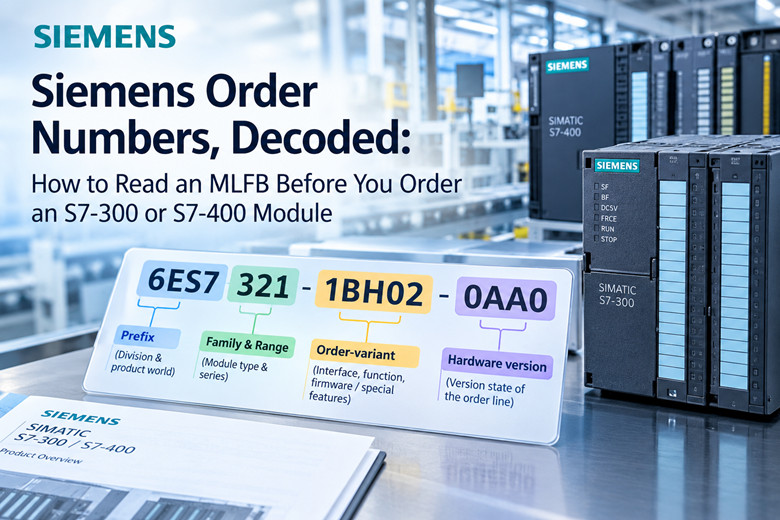
  • Siemens Order Numbers, Decoded: How to Read an MLFB Before You Order an S7-300 or S7-400 Module
    Siemens Order Numbers, Decoded: How to Read an MLFB Before You Order an S7-300 or S7-400 Module Sep 15, 2026
    An MLFB is a Maschinenlesbare Fabrikatebezeichnung, a German phrase that translates as machine-readable product designation. The term names the alphanumeric code Siemens assigns to a product so that catalogues, ordering systems, and logistics can identify that product without ambiguity. The string 6ES7 321-1BH02-0AA0 is an MLFB. It is the identifier a distributor quotes against, the string an online marketplace indexes, and the value a designer records in a bill of materials. When someone in a maintenance department says "the part number," the string they mean is normally the MLFB. Two distinctions belong at the very start, because confusion between them accounts for a large share of incorrect orders. First, an MLFB is not a serial number. A serial number identifies one individual unit and exists only once in the world. An MLFB identifies a product type, and every unit of that type ever built carries the same one. Second, an order number is not a description. "Analog input module, eight channels" describes a product; it does not identify one. The MLFB identifies one. Throughout the rest of this article, order number and MLFB are used as synonyms, which is how Siemens documentation itself uses them.   The block structure of a Siemens order number   A Siemens order number is not a single unstructured string. It is a sequence of blocks, and each block carries a defined piece of information. Reading an MLFB correctly means reading the blocks in order, from the prefix on the left to the trailing group on the right. The general shape is: 1. Prefix, for example 6ES, which names the division and the broad product world. 2. Integration level digit, for example 7, which marks the automation family. 3. Family and range digits, for example 321 or 315, which identify the module type and series. 4. Order-variant digits, which carry the interface code, the function code, and firmware or special-feature information. 5. Trailing hardware-version group, for example 0AB0 or 0AE0, which closes the string. A concrete example makes the abstraction manageable. Take 6ES7 321-1BH02-0AA0, a digital input module for the S7-300. The 6ES prefix states that this is an automation product from the SIMATIC world. The 7 states the integration level of the S7 family. The 321 states S7-300 digital input. The 1BH02 block carries the interface and function detail. The 0AA0 group closes the number and encodes the version state of that order line. Each of these blocks is examined below.   The prefix and the integration level   The 6ES prefix is the oldest and broadest of the automation prefixes. It covers the SIMATIC automation families across several generations, including S5, S7, M7, and the SC products associated with them. The digit that follows the prefix states the integration level. Where that digit is 7, the product belongs to the S7 family. This is why nearly every S7-300 and S7-400 module begins 6ES7, and why the two characters 6ES7 are effectively a family signature rather than a model indicator on their own.   The family and range digits   The next group of digits states which series and which module class the product belongs to. Within the S7 world, the range digits do the heavy lifting. A number in the 3xx block, such as 321, 322, 331, or 315, points at an S7-300 device. A number in the 4xx block, such as 421, 422, or 416, points at an S7-400 device. Note carefully that these are ranges, not single values. The module class is read inside the range: 321 is a digital input module, 322 is a digital output module, 331 is an analog input module, 332 is an analog output module, 307 is a power supply, and 315 is a CPU. The trailing digits inside the range refine the point count, the voltage class, and the electrical variant.   The order-variant blocks   After the range digits comes the order-variant area, sometimes written as the interface and function block. This section of the MLFB distinguishes modules that share a range but differ in connection, channel count, isolation, or special function. It is the block that separates a 16-point module from a 32-point module of the same class, or a standard unit from one with a diagnostic or interrupt capability. The final digits of this area, before the hyphen, often carry firmware or special-feature information. A reader who has learned the prefixes but stops reading here will still order the wrong device, because the variant block is where siblings diverge.   The trailing hardware-version group   The last group, separated by the hyphen, is the one buyers underestimate most. In 6ES7 321-1BH02-0AA0 the trailing group is 0AA0. The group encodes the hardware version state of the order line, and it also carries some packaging and configuration variants. Two strings that are identical up to that hyphen can describe physically different products. The next sections show that this trailing block is where length, pin count, and packaging differences hide, and it is the single most common source of an order that "looks right" and arrives wrong.   Prefix schemas differ by division   The block structure described above is a schema for the 6ES family. It is a mistake to assume that the same positions carry the same meaning under a different prefix. Siemens is a large company composed of divisions, and each division maintains its own prefix system. The 6ES prefix belongs to the SIMATIC automation world. The 6GK prefix belongs to SIMATIC NET communications, which covers SCALANCE switches and PROFIBUS components. The 6SL3 prefix belongs to SINAMICS drive products. The 6AV2 prefix belongs to HMI panels. A further series, 6ES7 288, identifies S7-200 SMART controllers, which live inside the 6ES world but follow conventions that are not those of the S7-300. The practical consequence is stated as a rule: field positions are not identical across the 6ES, 6SL, and 6GK families. A digit that means "digital input" in one schema can mean something unrelated in another. Learning to read one prefix does not transfer mechanically to its neighbours. The safe method is to read the prefix first, decide which schema applies, and only then interpret the blocks that follow.   Worked example: two products that differ only in the trailing group   The clearest demonstration of the trailing-group problem comes from the pre-wired front connectors used on S7-300 modules, because these parts share nearly everything except the final characters. The order number 6ES7 922-3BD20-0AB0 identifies the 20-pin pre-wired front connector. The order number 6ES7 922-3BD20-0AC0 identifies the 40-pin version. The string up to the hyphen is identical. The pin count is not. The two connectors also share the same cable specification: both are 3.0 m long, both use 0.5 mm2 PVC stranded wire, and both follow the DIN 47100 color code. If a buyer reads only the portion before the hyphen, the two parts are indistinguishable. The difference in usable channels is real, since a 20-pin connector cannot serve a module that expects 40 pins, and the error surfaces at the panel rather than at the desk. Length varies in the same position. The suffix 0AF0 marks the 5.0 m version of the connector, and 0AH0 marks the 8.0 m version. The connector is electrically the same part; the length is not. This is the general lesson: the last block is where length, pin count, and packaging variations are encoded. A trailing group is not decorative, and it is not interchangeable across lines.   Hardware and firmware revision digits   The trailing group carries hardware version information, and this has consequences that reach past physical fit into firmware behaviour. Two modules can be electrically compatible at the terminal and still behave differently from the point of view of the program that drives them. The revision letters inside the variant and trailing blocks are the markers of that difference.   The FM 350-1 counter module   Consider the FM 350-1 counter module. It was released across four successive order numbers: 6ES7 350-1AH00-0AE0, 6ES7 350-1AH01-0AE0, 6ES7 350-1AH02-0AE0, and 6ES7 350-1AH03-0AE0. These are the same module family. They are successive hardware revisions, and each is noted in Siemens documentation as version 1. The revision counter advances in the middle of the string, in the 1AH00, 1AH01, 1AH02, 1AH03 portion, while the trailing group stays constant at 0AE0. The example shows that revision information is not confined to the final group. It can appear in the variant block, which is why the whole string must be read rather than skimmed.   The CPU 315-2 DP case   The clearest practical case for a maintenance engineer is the CPU 315-2 DP. Two order numbers are in common circulation: 6ES7 315-2AG10-0AB0 and 6ES7 315-2AG14-0AB0. Both are sold and both are described as CPU 315-2 DP. They are not the same piece of hardware. They are different hardware revisions with different memory and firmware behaviour. This matters because a module that powers up is not automatically a drop-in replacement for the unit it replaced. If the STEP 7 project and the firmware in the rest of the rack expect a specific revision, a compatible-looking substitute may introduce behaviour the program was never tested against. The lesson generalizes to every CPU and every function module: revision is part of the specification, not a footnote to it.   Where the MLFB is physically found   Siemens S7-300 documentation states that the order number and the version appear at the bottom end of the module front panel. On a module already installed in a rack, the front panel is the surface you can read without pulling the unit. That printed string is the authoritative source when you have the physical module in hand, and it should be copied character for character, including the hyphen and the trailing group. The MLFB is also visible in the hardware configuration of the STEP 7 project. When a project is opened, the module entries carry the order numbers of the configured hardware, which makes the project a second authoritative source. When a machine documents its original build, the project and the physical panel should agree. Where they disagree, the disagreement itself is diagnostic information. A third route is the Siemens Industry Online Support product search. Typing an MLFB into that search returns the product entry, which is where lifecycle status, successor products, and revision notes are recorded. This is the correct way to confirm what an order number actually denotes when a listing or a colleague provides only a bare string. The catalogue, the panel, and the project should be read together, and the MLFB is the key that connects all three.   Practical ordering rules   The following rules follow directly from the structure described above. They are stated as ordering discipline rather than as opinion. 6. Match the full MLFB character for character wherever the exact part is available. A match on the prefix and range alone is not a match on the product. The whole string identifies the item; a partial string identifies a family. 7. When only a different revision is available, check compatibility before committing. Confirm the firmware state of the target and the development system, and be prepared to perform a firmware update where it is supported and the project can absorb it. 8. Never order from a description alone. "SM331 analog 8 channel" is a description, not an order number, and it can map to more than one order line. A description narrows the search; the MLFB closes it. 9. Treat every identical-prefix different-suffix pair as a genuine difference until the catalogue proves otherwise. Trailing groups can encode packaging and version variants as well as function, so an identical-prefix module with a different suffix needs a catalogue check rather than a guess. 10. Record the MLFB in the maintenance file when a module is installed, not when it fails. The person who needs the number most is the person under time pressure, and the panel is hard to read from the aisle. For S7-300 and S7-400 spares specifically, a parts source that publishes full order numbers rather than loose descriptions removes a large share of the guessing. A catalogue organized by MLFB, such as the one at Siemens parts listings, lets you match the string you read off the panel against the string being sold.   Reference table: common S7-300, S7-400 and adjacent modules   The table below lists commonly requested modules with their exact order numbers. Every order number in the table is a real string; the function column is a plain-language summary, and the notes column flags anything a buyer should read before ordering. When you need a module in a PLC system, matching against a reference list of this kind at PLC listings is faster than reading each description in isolation. Module | Order number (MLFB) | Function | Notes SM321 DI 16xDC24V | 6ES7 321-1BH02-0AA0 | Digital input, 16 points, 24 V DC | Standard 16-point DC input for S7-300; wiring sets the sink or source behaviour SM321 DI 16xDC24V, source input | 6ES7 321-1BH50-0AA0 | Digital input, 16 points, 24 V DC, source variant | Same range and point count as the 1BH02; the variant block differs, so the electrical connection does too SM321 DI 16xAC120/230V | 6ES7 321-1FH00-0AA0 | Digital input, 16 points, 120/230 V AC | AC input module; the voltage class sits in the variant block, not the range digits SM321 DI 32xDC24V | 6ES7 321-1BL00-0AA0 | Digital input, 32 points, 24 V DC | 32-point density; verify terminal and connector requirements for the point count SM322 DO 32xDC24V/0.5A | 6ES7 322-1BL00-0AA0 | Digital output, 32 points, 24 V DC, 0.5 A | Output module of the same density; range 322 marks digital output SM323 DI16/DO16 | 6ES7 323-1BL00-0AA0 | Combined digital input and output | Combined module; the 323 range denotes the mixed input/output class SM331 AI 8x12bit | 6ES7 331-7KF02-0AB0 | Analog input, 8 channels, 12-bit | Range 331 marks analog input; 12-bit resolution is stated in the variant block SM332 AO 4x12bit | 6ES7 332-5HD01-0AB0 | Analog output, 4 channels, 12-bit | Range 332 marks analog output PS307 2A | 6ES7 307-1BA01-0AA0 | Power supply, 24 V DC, 2 A | Supply module; current rating is read from the variant block PS307 5A | 6ES7 307-1EA01-0AA0 | Power supply, 24 V DC, 5 A | Same range as the 2 A unit, higher current; the two differ inside the variant block CPU 314 | 6ES7 314-1AG14-0AB0 | CPU, compact class | CPU range 314; revision letters appear before the trailing group CPU 315-2 DP | 6ES7 315-2AG10-0AB0 | CPU with PROFIBUS DP interface, earlier hardware revision | Described identically to the 2AG14 in many listings, but a different hardware revision CPU 315-2 DP, later revision | 6ES7 315-2AG14-0AB0 | CPU with PROFIBUS DP interface, later hardware revision | Differs in revision from the 2AG10; confirm project and firmware expectations before substituting IM 153-1, ET 200M | 6ES7 153-1AA03-0XB0 | Interface module for ET 200M distributed I/O | Trailing group 0XB0, the pattern seen on ET 200 family modules, unlike the 0AB0 on S7-300 modules FM 350-1 counter | 6ES7 350-1AH03-0AE0 | Function module, counter | Revision information sits in the variant block (1AH03); the trailing group is 0AE0 SM 1231 AI 4xRTD (S7-1200) | 6ES7 231-5PD30-0XB0 | Analog input for S7-1200, four RTD channels | Belongs to a different controller generation; do not read its blocks using S7-300 conventions S7-200 SMART CPU SR20 | 6ES7 288-1SR20-0AA0 | Compact CPU for the S7-200 SMART series | The 6ES7 288 series is its own schema within the 6ES world PROFIBUS DP connector, 90 degree outlet | 6ES7 972-0BA12-0XA0 | Bus connector for PROFIBUS DP | Accessory part; the 0XA0 trailing group marks a distinct packaging and variant class Two patterns deserve comment. The first is that a single range contains several variant blocks, and the 321 rows show it. The second is that trailing groups are not uniform across families: 0AB0, 0XB0, 0AE0, and 0XA0 all appear above, and they belong to different families and accessory classes. The last block is read in the context of the prefix, not in isolation.   Buying old stock: why the exact string is the search key   Online marketplaces and surplus sellers index modules by the exact MLFB string. The search engine does not know that you meant a 40-pin connector when you typed a 20-pin number, and it does not know that a revision letter matters to your project. It matches characters. This means the exact MLFB is the search key, and nothing softer than the exact string reliably returns the right part. Revision differences are where surplus purchases go wrong most often. A listing that shows a photograph of a module which looks correct can carry an order number one revision away from the one you need. Because a surplus item is usually a single physical unit, there is no second unit behind it to correct the mistake. Verify the printed string in the listing against the string on your panel or in your project before payment. Before paying a premium for old stock, confirm the lifecycle status of the order number through Siemens Industry Online Support. That portal records whether a product is active, phased out, or discontinued, and whether a successor is named. Lifecycle status is the fact that determines whether a premium is justified. A module that is no longer supported is worth what availability costs; a module with an active successor is worth no more than the successor.   Rules of the catalogue   The ten points above compress into a short set of rules for reading any Siemens order number. 11. An MLFB identifies a product type; a serial number identifies a single unit. Do not confuse the two. 12. Read the blocks in order: prefix, integration level, range, variant, trailing group. 13. The prefix decides the schema. 6ES, 6GK, and 6SL do not share field positions. 14. The range digits name the family and module class; the variant block distinguishes siblings. 15. The trailing group carries versions, lengths, pin counts, and packaging. Read it every time. 16. Revision letters can sit in the variant block as well as the trailing group. The whole string matters. 17. Order by exact string. A description narrows the search; the MLFB closes it. 18. A powered-up substitute is not automatically a compatible one. Check revision against the project and firmware. FAQ Where do I find the MLFB on my module? On S7-300 modules, the order number and the version appear at the bottom end of the front panel, where they can be read with the module installed. The STEP 7 hardware configuration also carries the order numbers of every configured module, so an open project is a second source. A third source is the Siemens Industry Online Support product search, which returns a product entry when you type an MLFB into it. What is the difference between an MLFB and a serial number? An MLFB is a product-type designation. Every unit of that type shares it. A serial number identifies one individual unit and appears only once. The MLFB is what you order; the serial number is what you would cite if you needed to trace one specific unit through service or warranty. Does the last block of the order number matter? Yes. The trailing group carries version state, length, pin count, and packaging variants. The 20-pin front connector 6ES7 922-3BD20-0AB0 and the 40-pin 6ES7 922-3BD20-0AC0 differ only there, and the 0AF0 and 0AH0 suffixes mark the 5.0 m and 8.0 m lengths. An identical prefix with a different trailing group is a different purchase. Can I fit a 315-2AG14 where a 315-2AG10 came out? Both carry the description CPU 315-2 DP, but they are different hardware revisions. Physical fit is not the only question; the STEP 7 project and the firmware in the rack expect a defined revision behaviour. Check the compatibility of the revision against your project before treating the substitution as equivalent, and be prepared for a firmware update where the system supports one. Why do two listings for the same module end differently? Because the listings are not for the same module. A difference in the trailing group signals a difference in version, length, pin count, or packaging, so two listings that agree everywhere except the final characters describe two distinct order lines. Treat the divergence as meaningful and check the catalogue rather than assuming the cheaper listing is equivalent. Are 6ES7 and 6ES5 the same thing? No. Both sit under the 6ES automation prefix, but the integration-level digit separates the generations. 6ES5 belongs to the S5 generation and 6ES7 belongs to the S7 generation. A part from one generation is not an order-number match for the other, and the internal block meanings do not transfer. What do I do if the exact revision is unavailable? Establish what the exact revision is from the panel, the STEP 7 project, or the Industry Online Support entry. Then check whether the nearest available revision is documented as compatible with your configuration. Confirm the firmware state of the replacement, plan for an update if needed, and verify the lifecycle status of both the original and the substitute before committing to a surplus purchase. Does the order number appear anywhere else besides the panel? The Module Information dialog inside STEP 7 reports the order number of an online module, which is useful when the panel is difficult to read. The project configuration and the Industry Online Support search cover the offline case. Where all three sources are available, they should agree; where they differ, the panel printed in the factory is the authority for what is physically installed. ------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).  
  • Mitsubishi FX2N in 2026: The 1991 Brick That Refuses to Die
    Mitsubishi FX2N in 2026: The 1991 Brick That Refuses to Die Sep 11, 2026
      Think about what else from 1991 is still clocking in every morning. A fax machine in a government office, maybe. A bearing press that nobody has the manual for. And, in tens of thousands of plants from the Gulf to the Great Lakes, the Mitsubishi FX2N: a dark gray plastic brick, roughly the size of a thick dictionary, with a round eight-pin programming port on the front, and no screen, no menu, no opinions. Mitsubishi launched the FX2N in 1991 as its mid-range micro PLC. The engineer who commissioned yours has retired. His apprentice has retired. The person who troubleshoots it today was not born when the unit shipped, and that person is probably working on a laptop that is newer than the machine's entire electrical room. Yet the brick keeps scanning. Packaging lines in Dubai run on it. Water skids in Texas run on it. Injection molding auxiliaries in Egypt, conveyor systems in Poland, OEM equipment scattered across the Middle East, Asia, Africa and Eastern Europe all run on it. Here is the situation nobody at headquarters wants to admit. Mitsubishi discontinued the FX2N long ago. It was replaced by the FX3U, and then by the FX5U and the iQ-F platform, and each generation made the old one harder to love: different software, different wiring, a different way of thinking. New old stock FX2N parts get scarcer every year and the surplus prices creep up. And still the machines run. I am not sentimental about this hardware. It is old. It is slow. It has no Ethernet port, no web server, and it will never get either. But it is paid for, it is wired, it is proven, and it does not reboot itself on a Tuesday because of an update nobody approved. Half the time a plant calls me about a "dead" FX2N, the PLC is fine and the panic is not. The other half, the fix is a battery, a cable, or a spare module that should have been sitting on the shelf for years. So here is the working knowledge, the way I would hand it to an engineer across a greasy bench. Six things you need to understand about the FX2N in 2026, then the spares shelf that keeps a plant full of them alive.   1. Why This 1991 Brick Refuses to Die   The FX2N refuses to die for a boring reason: there is almost nothing inside it that can die. It does one thing, which is scan. It reads the inputs, executes the ladder rung by rung, writes the outputs, and does it again. That loop is the entire product. There is no operating system to patch, no firmware update that can brick it, no boot sequence that can hang, no cloud service that can go end of life and take your machine down with it. An FX2N powers up and is running your process in the time it takes a modern screen to finish animating its logo. The program itself lives in EEPROM. That detail matters more than almost anything else on this list, because it is the most misunderstood thing about the whole platform. The ladder is not held in RAM and it is not held in the battery. Cut the power, drop the battery, ship the PLC across an ocean in a box of rags: the program is still there when it arrives. Mitsubishi built the FX2N with 8,000 steps of program memory as standard, bigger jobs went onto an optional EEPROM cassette, and in every case the program storage was non-volatile by design. Power loss was never the enemy of the program. The fear that "the program vanished when the power dipped" is almost always really a story about something else: a dead battery wiping latched data, which section 2 covers, a bad upload overwriting good code, which section 3 covers, or a memory cassette that died of old age. The rest of the design is honest industrial engineering. The device map is flat and easy to hold in your head: X for inputs, Y for outputs, M for internal relays, D for data registers, T for timers, C for counters, with the special relays like M8000 doing system chores. The instruction set is small enough that one person can carry it around in their skull for thirty years. The base units came in sizes from the FX2N-32MR up through the FX2N-64MR and the FX2N-80MR, with the FX2N-32MT and its transistor-output siblings for the high-cycle jobs. I/O expansion snaps onto the side of the base, and special function modules like the FX2N-4AD and the FX2N-4DA hang off the same bus and get talked to with FROM and TO instructions. And the mechanical side shrugs off what kills newer gear. No fan to clog, no hard drive, no touchscreen to crack, no SD card to corrupt. A sealed brick with terminal screws. Put it in a cabinet hot enough to make a modern smart relay complain, and the FX2N just sits there scanning, the way it has since the first Bush administration. That is why the brick outlives engineers: nothing about it is fragile except the parts this article is actually about. The battery, the software path, the comm boards, the output devices, the power supply capacitors. Those are the failure points, and they are all manageable if you treat them like the wear items they are.   2. What the F2-40BL Battery Actually Protects (and Which Fear You Can Drop)   Ask a room of maintenance engineers what the F2-40BL battery protects in an FX2N, and half of them will tell you it keeps the program alive. It does not. Repeat that to yourself the next time someone wants to panic-download a program at two in the morning because the battery light came on. The program is in EEPROM, as section 1 just covered. What the F2-40BL actually backs up is the latched data area: the M relays and D registers that were marked as latched in the PLC parameters, the counters that hold production totals, and the real-time clock on the models that carry one. Lose the battery and you lose those values. The ladder comes back untouched and runs, and then your machine starts with zeroed totals and whatever default register values the program assumes, which can be its own kind of exciting if a recipe lived in latched D registers. Mitsubishi flags a low battery through a special relay, M8006 on the FX2N family, and that flag latches once it trips, so it does not quietly un-trip itself after you ignore it for three weeks. When you see it, deal with it. The battery itself lasts years in a normal cabinet. Heat is what kills it early, so the plant with the FX2N bolted next to the oven door changes batteries more often than the plant with the climate-controlled panel. That is not a fault in the battery, that is physics. The exchange procedure is where field lore saves data. Do it with the PLC powered on. With power applied, the CPU keeps the RAM alive from its own supply, so you can unclip the old F2-40BL, clip in the new one, and lose nothing. The board also carries a capacitor that gives you a grace period if you insist on swapping dead, but do not bank your production totals on a grace period. Power the unit up and swap it live. It takes ninety seconds and it is the whole trick. One more piece of honesty. If a battery has been dead for a long time and the machine starts acting brain-damaged, the answer is not a new battery and a shrug. The latched values are gone. You need to re-teach setpoints and totals, and that is exactly why the smart plants keep a written record of what those values should be, or load them from parameters stored in the program, or both. A dead battery is a nuisance. A dead battery with no record of the latched values is a bad afternoon.   3. The Software Fight: GX Developer, Windows 11, and the SC-09 Driver Lottery   Now the part that makes young engineers cry: talking to the brick at all. The FX2N was programmed with GX Developer, or with the even older FXGP/WIN for the true veterans, and that is still the truth in 2026. The FX2N generation never got proper support in the newer software. GX Works2 was built for the FX3U and FX3UC generation and the FX3G family; the FX2N was left out of that party, or only half-welcomed depending on the regional build. GX Works3 belongs to the FX5U and the iQ-F world entirely. So the tool for an FX2N today is still GX Developer, a program whose last heyday was the Windows XP era. Running GX Developer on Windows 10 or 11 is a battle. Sometimes it installs and behaves. Sometimes it installs and crashes the moment you open a project. Sometimes the installer itself throws a compatibility fit that no amount of right-clicking "run as administrator" fixes. The reliable path is a virtual machine with Windows XP or Windows 7 on it, with the USB passed through to the guest, and GX Developer living its best life in 2004. If you have an actual old laptop with a real serial port, you own a treasure. Label it, and keep it in a drawer that nobody borrows from. Then comes the cable. The FX2N programming port speaks the FX serial protocol on an eight-pin round connector, and the official way in was the SC-09, a converter box that sat between that port and a PC serial port. The genuine SC-09 is long gone from the catalog, and what you actually buy in 2026 is a USB clone. The clone market is a driver lottery. Some clones carry CH340 chips, some carry Prolific chips, some claim FTDI, and some are counterfeit FTDI chips that modern Windows refuses to load drivers for at all. You can spend an afternoon installing three different driver sets and still end up staring at a "device cannot start" error. Field rules for the cable fight. Buy the cable from someone who sells it as a PLC cable, not as a random USB doodad. Keep the COM port number low, because old GX Developer gets grumpy about high port numbers. Match the baud rate to what the PLC parameters expect. And never plug the cable into a powered FX2N unless you know the adapter is isolated. The genuine SC-09 had isolation on the PLC side. Many of the cheap clones do not, and one good ground loop from a laptop sitting on a flaky earth can fry the programming port on the PLC. That turns a twenty-dollar cable problem into a three-hundred-dollar CPU problem, and I have watched it happen twice. Power down the PLC, connect, power up. That habit alone saves a plant more money than any other tip in this article. Archive the program properly while the software still runs. Upload from the PLC, save the project file in two places, export a text listing, and print a copy that lives inside the electrical cabinet if you have any sense. The day will come when the only copy of that program sits on a laptop that will not boot, and the machine will not care about your feelings.   4. The Modules That Are Drying Up   The base unit is only half the machine. Around it hangs the ecosystem that made the FX2N a mid-range workhorse instead of a toy: analog modules, comm boards, extra I/O. This is where the shortage hurts most, because the base CPU was built like a tank but the ecosystem around it is disappearing faster than the bricks themselves. The FX2N-485-BD was the workhorse comm board, giving the PLC an RS-485 port for talking to variable frequency drives, HMIs, and other PLCs, including the FX2N's simple N:N network between multiple units. The FX2N-232-BD added a real RS-232C port for barcode scanners, printers, and PC links. The FX2N-4AD brought in four analog inputs and the FX2N-4DA four analog outputs, and if your machine reads a pressure transmitter or drives a valve positioner, you know exactly which module I mean. On the I/O side, the FX2N-16EX and the FX2N-16EYR expanded the point count with input and relay output blocks, and the FX2N-16EYT was the transistor-output version for the high-cycle jobs. The FX2N-4AD-PT and the FX2N-4AD-TC handled Pt100 RTDs and thermocouples for the temperature crowd. Module | Job | Where you usually find it FX2N-4AD | Four analog inputs | Pressure, level, flow transmitters FX2N-4DA | Four analog outputs | Valve positioners, drive speed references FX2N-485-BD | RS-485 comm board | Drive links, HMI, multi-PLC N:N FX2N-232-BD | RS-232C comm board | Scanners, printers, PC link FX2N-16EX | Sixteen-point DC input block | I/O expansion FX2N-16EYR | Sixteen-point relay output block | I/O expansion, switching loads SC-09 | Programming cable and converter | Talking to the PLC at all None of these are in Mitsubishi's active catalog anymore. What is left is new old stock, and it is disappearing. A plant that waits until a 485-BD dies to go shopping will pay whatever the last seller on the internet asks. A plant that buys spares while the parts are merely scarce gets to choose. When you see new old stock of the modules your plant actually runs, buy it then, not when the smoke lets out. One thing that makes stocking easier: special function modules are addressed by position on the bus and driven with FROM and TO instructions, so a replacement module does not need to match the original serial batch. The program talks to position four the same way whether the module in position four was shipped in 1998 or 2004. Mind the station switches and the settings, and a swap takes minutes instead of a rewrite. When you go hunting for this stuff, the Mitsubishi PLC parts category is a decent place to start. They stock FX2N CPUs, I/O blocks, comm boards and batteries, the legacy Mitsubishi aisle that the big distributors stopped bothering with years ago.   5. What Actually Breaks in the Field   After decades of field calls, here is what actually kills FX2Ns, roughly in the order I have seen it. Power supply capacitors come first. The FX2N's internal power supply is a switching supply designed in the 1990s, and after decades of heat the electrolytic capacitors age: the electrolyte dries, the ripple climbs, the rails sag. The classic symptom is a machine that resets when the big contactor pulls in, or outputs that drop for a blink, or comms that fall over for no reason anyone can explain. Many of the "the PLC is dying" calls I have taken were just a power supply full of tired capacitors. A handful of new capacitors and a soldering iron brings the brick back for another decade. If you cannot solder, that is what the spare CPU on the shelf is for. Welded relay outputs come second. After millions of operations switching contactor coils and solenoid valves, the relay contacts inside an FX2N-32MR or an FX2N-16EYR eventually weld shut. The symptom is an output that will not drop out: the ladder says off, the load stays on. This is not a defect, it is a wear item, and a solenoid valve cycling ten times a minute burns through the mechanical life of a relay faster than most people believe. The fix is a module swap, and the lesson is that relay output life is rated in operations, not in years. Blown transistor outputs come third, and they are usually a wiring crime. On the MT units, inductive loads without flyback diodes across the coil will eventually kill the output device, shorted or open, and a shorted output can take its common with it. Before you blame the PLC, check the suppressor across the contactor coil. The PLC was doing what it was told; the coil was biting back. Fried programming ports come fourth, and section 3 already explained the cause: non-isolated USB-serial adapters plugged into a live PLC. The fix is a habit, not a part. Power down, connect, power up. Teach it to everyone who touches the machine. Then come the boring failures that outnumber all of the above. Loose terminal screws after years of thermal cycling. Dust. A 24V DC sensor supply that sags until inputs start misbehaving. A blown fuse that everyone walks past for an hour. An extension cable between the base and an expansion block that got crushed when somebody worked in the cabinet. Power supply first, then the 24V rail, then wiring and fuses. Only then blame the CPU. And when the ERROR LED on the front is blinking at you, read the error code before you start throwing parts at the panel. The blinking pattern and the special data registers will tell you what the CPU thinks is wrong, and the CPU is usually right about that part.   6. The Honest Math: Keep Running or Migrate   At some point, in every plant that runs FX2Ns, the question arrives: do we migrate this thing or keep it running? Sit down and do the math before the marketing department does it for you. Start with the cost of doing nothing. A used or new old stock FX2N CPU from a decent surplus house costs a fraction of what one afternoon of line downtime costs, and it drops into the same rail, the same wiring, and the same program. If the machine makes money and the process works, replacing the PLC is not an upgrade. It is a project with a risk profile, and every migration I have ever seen introduced at least one new failure mode that did not exist before. Old gear fails in ways you know. New gear fails in ways you get to learn. If you do migrate, know what each path actually costs you. The FX3U is the closest thing to a natural successor, and it is still not a drop-in. It is not pin-compatible with the FX2N. The terminal layout differs, the mounting differs, and every wire gets re-terminated and re-checked. The program side is friendlier: the FX family kept broad instruction compatibility, so much of the ladder carries over, but anything that touches the special function modules, the comm instructions, or the old device map needs a careful pass, and every FX2N expansion module on the rail has to be checked against the FX3U compatibility list. Call it a re-wire with a program conversion, not a swap. Programming software | GX Developer or FXGP/WIN | GX Developer or GX Works2 | GX Works3 Wiring | Baseline | Re-terminate everything | Re-terminate everything Old program reuse | Baseline | Partial, needs a conversion pass | Full retype in a new environment Built-in ports | Serial programming port | USB and serial | Ethernet onboard The FX5U and the iQ-F platform are a different country. GX Works3, structured projects, a new way of organizing programs, a full retype of the logic, and new wiring on top of it. What you get in return is Ethernet onboard, which is genuinely worth something if the plant wants data collection or modern HMI protocols that the FX2N simply cannot speak. The FX2N has no Ethernet and never will. If the process needs to talk to the business systems, that is a real reason to migrate, not a fashion statement. So the honest triggers for migration: when the spares that matter are gone and failures start stacking up; when the machine needs comms the FX2N cannot do; when the person who actually understands the program is retiring and the documentation is thin, because migrating while that person still works is ten times cheaper than migrating after; and when the machine is being rebuilt anyway. Then migrate in daylight, with a plan, and keep the old unit intact until the new one has run a full production week without a fault. A running FX2N is a reference document you can touch. And while you run the mixed fleet that most plants actually have, old bricks next to new gear in the same cabinet, it pays to standardize where you buy. The industrial automation side of a good supplier carries the modern stuff, and the Mitsubishi aisle carries the legacy stuff, and both end up on your panel eventually.   The Spares Shelf Every FX2N Plant Needs   If your plant runs several FX2N units, build the shelf before the failures, not after. Here is what a plant that runs a family of FX2N machines should stock, and I would defend this list against any distributor's upsell. Item | Stock | Why it earns its place Spare FX2N CPU, the model of your most common base, FX2N-32MR, FX2N-64MR or FX2N-80MR as applicable | One per plant | A dead CPU becomes a thirty-minute swap instead of a three-day emergency FX2N-485-BD comm board | One | The most wanted comm board on the surplus market, and the one that dries up first SC-09 or a known-good USB clone cable | One spare | Cables die, get lost, and get borrowed, and the driver lottery waits for nobody F2-40BL batteries | Two | Change them the day M8006 trips and you never lose a latched value again FX2N-16EYR relay output block | One | Welded relays are a when, not an if, on high-cycle machines FX2N-4AD, if you run analog | One | The module you will not find quickly when a transmitter loop starts reading nonsense Program backups | Keep forever | Project files in two places plus a printed listing in the cabinet Where does that stock come from in 2026? Mitsubishi's catalog is closed to the FX2N, so the honest answer is the surplus channel: new old stock dealers, brokers, machine rebuilders, and the specialists who made legacy Mitsubishi their whole aisle. When you find a PLC spare parts supplier who actually has FX2N stock, verify what they ship, then buy the shelf list, because the market only moves in one direction. The FX2N is not going to outlive you. Nothing does. But it will absolutely outlive your excuses for not owning a spare CPU, a fresh battery, and a cable that works. The machine out on the floor does not care that the platform is retired. It cares about the scan. Keep the shelf stocked, keep the program backed up, keep the battery fresh, and that 1991 brick will keep paying its way while the accountants argue about what to replace it with. That is not nostalgia. That is just good maintenance. URL Slug: mitsubishi-fx2n-still-running-guide -------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).  
  • ControlNet Troubleshooting: A Field Procedure That Gets the Net Back
    ControlNet Troubleshooting: A Field Procedure That Gets the Net Back Sep 09, 2026
      At 2:17 in the morning the phone wakes you, and the voice on the other end skips the hello. Node 14 dropped and the line is down. Scheduled traffic through the 1756-CNB stopped forty minutes ago, the drives are faulted, and the shift electrician has already reseated every connector he can reach. He wants to know if you are coming. You are coming. Before you get in the truck, take this article with you. Here is the situation you will walk into. A ControlNet trunk built from 1786-RG6 coax, tapped into a row of 1756-CNB and 1756-CNBR modules in ControlLogix racks, a 1788-CN2DN or two carrying I/O down to DeviceNet, and a schedule that RSNetWorx for ControlNet wrote years ago and nobody has backed up since. Rockwell lists ControlNet as Active-Mature, which is a polite way of saying it still supports the product but is not building more of it. The company would rather sell you EtherNet/IP on 1783 switches, and it is right to try. But your plant still runs on coax, and it has to run tomorrow. This is the field procedure that gets the net back. Do the steps in order and do not skip the boring ones, because the boring ones are where these calls usually die.   Tools you need before you start   Round these up before you leave the shop. Every trip back to the truck for a missing part costs twenty minutes of a night that is already long. · RSNetWorx for ControlNet, installed and proven on your laptop. Know which version you carry, and know that the EDS files on that laptop match the devices on the net. A laptop that has not seen the plant in two years will waste your first hour updating itself. · A ControlNet interface for the laptop. The 1784-PCC CardBus card and the 1784-U2CN USB adapter are the two you will meet in the field. Load the driver and configure it in RSLinx before you leave, and test the card against a live net at the shop. Testing it for the first time in a dark panel at 3 AM is a bad plan. · The backup schedule file. This is the .cnc file that RSNetWorx saves when you commission a network. If you do not have one, your night just got longer. If you have one but it is five years old, treat it with suspicion until you have compared it to the running network. · Physical spares: a short length of 1786-RG6 coax, two 75-ohm terminators, one spare tap, and a handful of BNC connectors. Take a full drum of cable if the trunk is long or runs outdoors. · A known-good 1756-CNB or 1756-CNBR, flashed to the firmware your plant runs, in case step 6 becomes necessary. · A multimeter, a flashlight, a small mirror for reading node addresses behind panels, and the EDS files for every third-party device on the net, carried on a USB stick.   Run the ladder in this order   ControlNet faults fall into four bins: the cable, the module, the schedule, and the node. The failure modes look alike from the operator screen, and that is the trap. A node that dropped because a terminator is missing looks identical to a node that dropped because its address collides with another node. The order of attack is not a preference. Check the physical layer first, then the module, then the schedule, then the node, and swap hardware last. Each step eliminates a whole class of faults, and none of them requires you to trust the story the operator told you at 2 AM.   Step 1: Check the physical layer first   ControlNet is a scheduled, time-sliced network running 5 Mbit/s on 75-ohm coax. Every node gets a guaranteed slot in a repeating frame, and the whole scheme depends on the signal arriving clean at every tap. Reflections kill that signal, and reflections come from bad geometry: open ends, wrong cable, stubs, water. Most "the net went down at 2 AM" calls end here, in the cable, not in the schedule. Start at one end of the trunk and work your way to the other. Power down what you can before you touch coax. Do not hot-unplug a live trunk while the plant is depending on it, and never pull a connector to "see if it sparks." It will not spark, and you will have just dropped the net. Check the terminators first. A ControlNet trunk needs exactly two, one at each physical end, and both must be 75 ohm. The 1786-XT is the correct part for this system. A missing terminator leaves the end of the cable open. The signal reflects off that open end, and nodes near it go marginal and drop when the cabinet warms up or a large motor starts. An extra terminator is just as bad when it hangs off a tap in the middle of the trunk, because it turns a healthy segment into two stubs. The rule is short: two terminators, at the ends, nothing else on the cable. Check every BNC connector on the trunk. Seated means you feel it click into place and you cannot rotate the shell against the jack. A connector that spins is a crimp that failed years ago and has been getting worse since. Look at the center pin. It should be clean, straight, and fully engaged. Water in a connector reads as intermittent loss that no schedule change will ever fix, and corrosion on the shield braid does the same. When you find a bad connector, cut it off and re-terminate with a fresh one rather than tightening it and hoping. Check the cable itself. The trunk must be 1786-RG6 quad-shield coax. RG-59 will carry the signal a short way and then lie to you, and the leftover TV coax someone used to patch a broken section is worse than no patch at all, because it passes the DC checks and fails under load. If someone spliced the trunk with a barrel connector, that splice is a reflection point and a future 2 AM call. If someone daisy-chained from one module's BNC straight to the next module's BNC instead of using taps, you are looking at a stub that should never have been built. Devices attach through taps, with a short drop cable from the tap to the node. Keep every drop to a meter or less and route it clear of power cables. Then run the numbers. A single ControlNet segment is limited to 1000 m of RG-6 and 48 nodes. If your plant exceeds either limit, a repeater must sit in the path, and the problem node is probably on the far side of that repeater. Look for the repeater and check its power before you go any deeper. While you are walking the cable, look for the obvious damage: coax crushed behind a swing panel, cable routed through a drain, water standing in a below-grade pull box, a fork truck scar on the jacket. ControlNet cable failures are rarely mysterious once you look at the actual cable. If the whole net will not come up, you are hunting a short or an open. Every node's network LED dark or flashing at the same time means the trunk is the problem. It is not forty modules that all failed in the same hour. Isolate the fault methodically. Power down nodes one at a time, pull their drops at the tap, and watch whether the rest of the net comes solid green. When you pull the drop that fixes the net, you have found the guilty piece. It is usually a crushed cable, a wet connector, or a tap that took a hit from a ladder. Fix that one thing and the net comes back whole.   Step 2: Read the module LEDs   The 1756-CNB and 1756-CNBR tell you a lot from the front panel if you read the indicators in pairs. The 1756-CNB carries two indicators, one for module status and one for network status. The 1756-CNBR carries three: module status plus one per redundant channel. The module LED tells you whether the hardware is alive. The network LED tells you whether it is talking. Read the module LED first. A module that is dead on the backplane will never talk on the net, no matter how good the cable behind it is. Indicator | Pattern | What it means | What to do Module LED | Off | No power, or the module is not seated on the backplane | Reseat the module firmly. Check the chassis power supply and the slot. Module LED | Solid green | Normal operation | Nothing. Move to the network LED. Module LED | Flashing green | Self-test in progress, or firmware being updated | Wait. If it still flashes after ten minutes, cycle power to the chassis. Module LED | Flashing red | Recoverable fault, usually configuration or firmware related | Check the firmware revision against the I/O tree in Studio 5000. Cycle power. Module LED | Solid red | Unrecoverable fault | Reseat once. If the red returns, the module is dead. Go to step 6. Network LED | Off | Module is alive but not talking on the trunk | Check the tap, the drop cable, and the trunk behind this node. That is step 1 work. Network LED | Solid green | Online and passing scheduled traffic | Normal. Nothing to do. Network LED | Flashing green | Powered but not communicating with the network | The node cannot hear the net. Check the terminator, the tap, and the node address. Network LED | Red, solid or flashing | Duplicate node address, or a serious network fault | Power the node down. Check its address against every other node. Check the trunk. On a 1756-CNBR running redundant media, the two network indicators should mirror each other. One solid green while the other shows red means the fault lives on that channel's cable or terminator, not in the module. Swap the suspect channel's cable and terminator before you condemn the module, and you will save yourself a part. One field rule carries you a long way. When every node on the net misbehaves at the same time, it is the trunk. When exactly one node misbehaves and the rest sit solid green, it is that node, its tap, its drop, or its address. Make that split early and you will not waste an hour working the wrong end of the ladder.   Step 3: Go online with RSNetWorx and verify the schedule   Get RSNetWorx for ControlNet online against the network before you change anything. Select the driver that matches your interface card, browse, and let the software discover the net. Write down what it finds: how many nodes, which ones are scheduled, which ones are not. That list is your map for the rest of the night. Then settle the question of who owns the schedule. On ControlNet, the schedule is the arrangement of who talks in which time slot. It lives in two places. The .cnc file holds it on whoever commissioned the network, and every scheduled node holds a copy of its own part. When RSNetWorx goes online and its file disagrees with the network, it asks which one to keep. If the network has been running fine and your file is stale, upload from the network and save it under a fresh name. If the network is the mess you were called to fix and your file is the good one, restore from the file. Make that decision once, deliberately, and say it out loud before you click. The wrong choice wipes a working schedule, and nothing in RSNetWorx will warn you twice. Open the network properties and read two numbers: the NUT and S_max. The NUT, or network update time, is the length of the repeating frame that carries all scheduled traffic. The default is 2 ms, and most plants never need more. S_max is the highest node address the schedule will accommodate. It must sit above your highest scheduled node. If someone added a node at address 60 while S_max sat at 50, that node will never be scheduled, no matter how many times you commission. Raise S_max, then commission. This one setting has sent more engineers in circles than any cable fault I have seen. RSNetWorx also shows the split between scheduled and unscheduled bandwidth. Scheduled traffic gets a guaranteed slot in every frame. Unscheduled traffic, the explicit messages, uploads, and programming traffic, fills whatever space is left. When a new connection will not fit the schedule, RSNetWorx tells you plainly. The fix is a larger NUT or fewer scheduled connections, never magic and never a second commission with the same numbers. While you are online, look at each scheduled node. RSNetWorx marks devices that are present but missing from the schedule, and it marks devices it cannot identify. Both conditions show up here first, and both have different fixes. If the net looks healthy in RSNetWorx, the problem is narrower than the phone call suggested, and step 4 will find it.   Step 4: Find the missing node   The plant says node 14 is gone. RSNetWorx says it sees 47 of 48 nodes. Do not trust the node number painted on the panel door. Trust the address the device is actually set to, because the two have disagreed since the day the panel was built. First, confirm the address. A 1788-CN2DN takes its node address from the switches on the device, and valid addresses run from 1 to 99. Write down what the switches actually say, not what the drawing says. A 1756-CNB holds its address in software, set through RSLinx or the module properties in Studio 5000. If the device's real address does not match the address the schedule expects, RSNetWorx will show the device sitting there healthy while the schedule ignores it completely. That mismatch produces exactly the phone call you got. Second, check for a duplicate. Two nodes on the same address is the classic intermittent fault. Both power up, one wins the slot, the other drops, and the drop rotates between them on every restart. If the missing node comes back the moment you power down its neighbor, you have a duplicate address. Change one node to a free address and re-commission. Do not put it off, because the duplicate will come back the next time both devices power cycle. Third, look at the tap. The drop cable from tap to node must be seated at both ends, and the node end is the one everybody forgets because it hides behind the module's own connector. A BNC that spins at the node end means a failed crimp. Replace the whole drop rather than re-crimping the old one, because the old one has been flexing for years and will fail again. Confirm the tap body itself is the right one for your trunk and that its clamp is actually closed on the coax. A tap that was installed but never tightened is a node that works until the cabinet door slams. Fourth, sort out what RSNetWorx is telling you, because its display is precise if you read it right. A device that appears as a question mark is present but unidentified. Its EDS file is missing from the machine running RSNetWorx, so the software cannot read its identity. Install the EDS file and refresh the browse. A device that appears with a name but no scheduled connections is not in the schedule, and that is step 5's problem. A device that does not appear at all is a physical problem, and that is step 1's problem. Work the step that matches the symptom. While you are standing at the node, look at the device itself and not just its connector. A 1788-CN2DN with a shorted DeviceNet side will drag down its ControlNet side, because the two share one processor. Check the node's own power supply as well. A drive or a linking device that is running on a dying 24 VDC supply will drop off the net in a pattern that looks exactly like a network fault. Put a meter on the node's supply terminals before you blame the trunk, and check it under load, not in a quiet moment between cycles.   Step 5: Fix the schedule and re-commission   Once the node is physically present and correctly addressed, the fix is to put it back into the schedule and write that schedule to every node on the net. That write is called commissioning, and it is the point of no return in RSNetWorx, because it downloads to every scheduled node at once. Start from the file. Open your backup .cnc and go online. If the backup is older than the running schedule, upload the running schedule first and save it under a new name before you touch anything. Then compare the two files and understand the difference. What you are about to do will overwrite the network, so you want to know exactly what you are overwriting and why. Put the network into edit mode in RSNetWorx, then look at what connections the controllers are requesting. This is the part that trips people up. The ControlNet schedule is built from connections the controllers actually request, and those requests come from produced and consumed tags that already exist in the controller logic. If the tag was deleted from the program months ago, no schedule entry in RSNetWorx will fix it. The connection has to be requested from the controller side first. Check the program in Studio 5000 before you blame RSNetWorx, and confirm the produced or consumed tag is still there, still enabled, and still mapped to the right node. With the connection requested and the node online, add the node to the schedule, confirm that S_max covers its address, and commission. RSNetWorx computes the schedule and downloads it to every scheduled node in one pass. Expect scheduled I/O to blip for a few seconds during the download. That blip is why you do this in a planned window when the line can afford it, not while the process is mid-batch. Verify after commissioning. Every scheduled node should sit solid green on its network LED. RSNetWorx should show a clean schedule with no unscheduled stragglers. The controller's I/O tree should show the connection running, and a test bit should actually move end to end. Then save the .cnc file, name it with the date, and put it somewhere the next shift can find it without calling you. Here is the lesson every ControlNet veteran has paid for at least once. The .cnc file is the network. Lose it, and a dead module becomes a two-day project, because a replacement module has to be added to a schedule that no longer exists anywhere except in the heads of people who have left the company. If you have no .cnc file at all and the net is currently running, go online right now and upload the schedule to a file. Do it before something dies, not after. Rebuilding a schedule from scratch means matching every produced and consumed tag in every program against physical nodes, and that job is always done once, at night, badly.   Step 6: Swap the module when it is dead   You have a 1756-CNB with a solid red module LED that survives a reseat and a power cycle. The module is dead, and the schedule is fine. Replace it. Before you pull it from the rack, record two things: the node address and the firmware revision. Both are cheap to read now and expensive to guess later. Get the address from RSLinx or from the module properties in Studio 5000. Get the firmware revision the same way, or from RSNetWorx while you are online. Then pull the old module and install the replacement in the same slot. Set the new module's address to match the old one before it joins the net. A fresh module sits at its default address until you tell it otherwise, and two modules sitting at the same default on the same network will fight exactly the way step 4 described. Flash the firmware with ControlFlash until it matches the revision the plant runs. If the I/O tree in Studio 5000 uses exact-match electronic keying, a revision difference will fault the connection even though the hardware is perfectly good. Attach the trunk, apply power, and watch the LEDs run through the sequence in step 2. The module LED should go solid green. The network LED should go solid green once it is passing traffic. Then go online with RSNetWorx and expect the new module to appear as a stranger standing at the old address. That is normal. If the schedule does not pick it up, commission from your backup .cnc exactly as you did in step 5, and verify the connection moves data before you call the job done. Keep the dead module out of the rack and decide what to do with it on a normal workday. A repaired module that fails again at 2 AM erases whatever you saved on the repair cost. Where does the spare come from? Not from the local distributor's shelf, because most distributors stopped stocking 1756-CNB modules the day Rockwell moved on. You keep one on your own shelf, tested and flashed, or you buy from a supplier that specializes in legacy Allen-Bradley hardware. That choice is the difference between a forty-minute swap and a week of expedited freight. The Allen-Bradley stock at tztechio.com is one place to look, and your own shelf is the better place to keep it.   Quick reference: symptom, cause, fix   Symptom | Likely cause | Fix Whole net down, every network LED dark or flashing | Missing or shorted terminator, water in the trunk, a tap drop shorting the segment | Step 1: check both terminators, then isolate taps one at a time One node drops at random and returns when it cools off | Marginal terminator, corroded BNC, failing node power supply | Step 1: reseat connectors, replace the drop, verify node power under load One node never appears in RSNetWorx | Address conflict or a dead tap | Step 4: read the actual address switches, walk the tap Node appears as a question mark | EDS file missing from the RSNetWorx machine | Install the EDS file, refresh the browse Node present but carrying no scheduled traffic | Node not in the schedule | Step 5: add the connection, commission Module LED solid red after reseat and power cycle | Dead module | Step 6: swap it, match firmware and address Net healthy but the controller faults the connection | Schedule changed under it, or module revision mismatch | Steps 5 and 6: re-commission, check electronic keying   ControlNet in 2026: run it, but plan the exit   Here is the honest picture. Rockwell's lifecycle status for ControlNet is Active-Mature. Support continues, and the installed base is huge, but new development stopped years ago and the catalog gets thinner every year. The company's direction is EtherNet/IP, and the 1783 family of switches and infrastructure is where new work goes. If you are designing a greenfield line, use EtherNet/IP and do not look back. Most of you are not designing a greenfield line. You are keeping a line that paid for itself years ago running while the plant decides what comes next. A migration off ControlNet is a real project with its own risks, and it does not happen at 2 AM when a node drops. If you are staying on ControlNet for another five years, run it like the critical utility it is: current drawings, tested spares, backed-up schedule files, and one named person who owns the network. If you are migrating, do it in a planned outage, prove the new path under real load, and keep the ControlNet trunk in place until the new one has earned your trust. Do not cut over on faith. The coax has carried this plant for two decades; the new network gets to prove itself before the old one is scrapped. For the racks that stay, the practical question is parts. ControlNet modules, coax, taps, and terminators are no longer made in the volumes they once were, and the PLC spares market is where legacy racks get fed. Buy what you need while it is findable, and treat the purchase as insurance rather than expense.   The spares shelf   Minimum shelf stock for one ControlNet network looks like this. One 1756-CNB or 1756-CNBR per network, flashed to the firmware your plant runs and tested before it goes on the shelf. One 1788-CN2DN if your net feeds DeviceNet through a linking device. A 30 m reel of 1786-RG6 coax, a handful of BNC connectors, and four 75-ohm terminators, because you will lose two before you need one. One spare tap of the style your panels actually use. The maintenance laptop, with RSNetWorx installed, the interface card tested, and every EDS file loaded. And the .cnc backups, on two different USB sticks, one of which lives inside the panel in a labeled bag. Check that shelf twice a year, in daylight, when nothing is broken. Test the spare modules in a live rack so you know they work. Refresh the USB sticks when the schedule changes. ControlNet is Active-Mature, which means the parts are not getting easier to find, and the industrial automation suppliers that still carry this generation of hardware are worth knowing before you need them, not after. Do the steps in order, keep the spares on the shelf, and keep the backup file where you can reach it at 2 AM. That is the whole job. The net will drop again. The question is whether you are ready for it the second time. URL Slug: controlnet-troubleshooting-guide -------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).  
  • S7-200 PLC Field Guide: The Faults a Veteran Technician Keeps Fixing
    S7-200 PLC Field Guide: The Faults a Veteran Technician Keeps Fixing Sep 08, 2026
      Last month I drove two hours to a feed mill because a dock leveler had stopped listening to its push buttons. The plant electrician had already told the boss the PLC was dead and they needed a whole new control system. I opened the panel, saw the little brick with the Siemens name on it, and got out my programming cable before I touched a meter. Twenty minutes later the leveler was cycling on its own. The CPU 224 was fine. The 24 V supply feeding the buttons had quit at lunchtime, and nobody had checked it because everybody was sure the PLC had died. That panel is the whole S7-200 story in one box. Siemens stopped selling these as new products more than a decade ago, and in 2026 there are still tens of thousands of them running pumps, gates, small packaging lines, HVAC skids and conveyor helpers all over the Middle East, the Americas and Europe. I have replaced more of these than I can count, and I have fixed ten times more than I replaced. Most of the faults are boring, predictable, and fixable in an afternoon with a meter, a screwdriver, and an old laptop running STEP 7 Micro/WIN. If you keep old plants running, this article is for you. I am not going to explain what a PLC is or how to write ladder logic. I am going to tell you what actually breaks on an S7-200 after ten or twenty years in a panel, how I find it, how I fix it, and what I stock so I do not have to scramble. When you do need a replacement CPU in a hurry, places like the PLC section at tztechio carry the old stock, but you want to know what you are buying before you buy. That comes later. First, the machine itself.   Why this old PLC refuses to die   The S7-200 came out in the middle of the 1990s as Siemens's answer to the little brick PLCs that were taking over small machines. It was cheap, it was tiny, and it did exactly one job. The later CPUs in the family, the 221, 222, 224, 224XP and 226, shipped from the late 1990s through the early 2010s, and they ended up inside an unbelievable number of machines. Three things keep it alive in 2026. First, the program does not live in battery-backed RAM like a lot of PLCs from that era. It lives in EEPROM on the CPU itself. No battery, no supercap, no memory that evaporates when the power goes off. You can pull a CPU 226 out of a machine, leave it on a shelf for five years, put it into another machine, and the old program is still sitting there waiting. Second, the software to program it, STEP 7 Micro/WIN, was free, and every maintenance electrician over the age of forty has a copy on an old laptop somewhere. Third, the whole family is cheap to replace from surplus stock, and the machines it runs are usually not worth re-engineering. Add all that up and you get a PLC that refuses to die. The machines around it wear out, the contactors wear out, the motors wear out. The little green brick just keeps scanning. When it does stop, the cause is usually around the CPU, not inside it.   The family and the hardware that matters   You need to know the family before you can diagnose it. Here are the five CPUs you will actually meet, with the order numbers you will see on the surplus market. The letters in the middle of the order number tell you the power supply and output type, and I never bothered to memorize that code. I read the sticker on the side of the CPU and the rating plate on the panel door. CPU | Common order numbers you will see | Onboard I/O | Expansion | PPI ports CPU 221 | 6ES7211-0AA23-0XB0 and 6ES7211-0BA23-0XB0 | 6 in / 4 out | none | 1 CPU 222 | 6ES7212-1AB23-0XB0 family | 8 in / 6 out | 2 modules | 1 CPU 224 | 6ES7214-1AG40-0XB0 (later two-port version), earlier 6ES7214-1AD23-0XB0 family | 14 in / 10 out | 7 modules | 1 or 2 CPU 224XP | 6ES7214-2BD23-0XB0 (DC/DC/DC), 6ES7214-2AD23-0XB0 (AC/DC/relay) | 14 in / 10 out plus 2 analog in and 1 analog out on board | 7 modules | 2 CPU 226 | 6ES7216-2BD23-0XB0 (DC/DC/DC), 6ES7216-2AD23-0XB0 (AC/DC/relay) | 24 in / 16 out | 7 modules | 2 The 221 is the little one with no room to grow. The 222 is the starter brick. The 224 is the one you find in nine panels out of ten. The 224XP is the favorite of machine builders because it has two analog inputs and an analog output built in, which saves a module and a wiring nightmare. The 226 is the big brother with forty points of I/O, and it is the one I tell people to stock as a spare because it replaces almost anything in the family with room to spare. Now the part that surprises people. The program is stored in the CPU's EEPROM, so it survives power loss and shelf time without any battery. The real-time clock and the retentive data are a different story. When the power is off, the clock and the retentive memory are kept alive by a supercapacitor, the little gold cylinder inside the CPU. On a fresh unit that supercap holds things for a few days, maybe a week. On a twenty-year-old CPU it might hold them for an afternoon. The optional battery cartridge, order number 6ES7291-8BA20-0XB0, stretches that to months for the CPUs that take it, which means the 224, 224XP and 226. Here is the sentence I repeat to panicking plant managers: a dead clock does not lose the program. Ever. I have walked into plants where the CPU had been dead for a year, the clock showed 2003, and the machine ran perfectly the moment power came back. The clock reset, the counters zeroed, and the program was right where it always was. Keep that in your head, because half the faults below look like they killed the program and almost none of them actually do.   The faults I keep fixing, in order   This list is ordered by how often I see each fault in the field, not by how interesting it is. The boring ones are at the top because they are the ones that cost you production.   Fault one: the 24 V DC supply gives up   This is number one by a wide margin, and it is the one that embarrasses electricians who tell the boss the PLC died. The DC-powered CPUs, the ones with DC/DC/DC in the name, need a clean 24 V DC supply between 20.4 and 28.8 V on the L+ and M terminals. They do not make their own power. When that external supply sags, dies, or gets set wrong, the CPU does strange things. It drops outputs, it forgets where it was, and if the supply is noisy enough it throws itself into STOP. I also see the reverse. The AC-powered CPUs, the AC/DC/relay versions, have a switched-mode supply built in, and after fifteen years the capacitors in that supply dry out. The CPU starts resetting itself when a contactor pulls in, or it refuses to start at all. The tell is the smell and the bulged cap when you pull the board, and the fix is usually a replacement CPU, because recapping an S7-200 supply is not worth your time. Then there is the onboard 24 V sensor supply. The CPU feeds a small amount of 24 V out to power your sensors, and when somebody shorts a sensor cable or overloads that little supply, the regulator dies. The CPU keeps running its logic, but every input that depended on that supply goes dead at once. The machine acts possessed. The first thing I check on any S7-200 with a handful of dead inputs is whether the sensor supply voltage is present at the terminals. It is amazing how often that is the whole fault. Fix it by measuring first. Check voltage at L+ and M right on the CPU terminals with a load connected, not open circuit. A supply that reads 24 V with nothing on it can sag to 18 V the moment sensors and an output card start drawing. Set the supply to 24.5 V and leave it alone. If the CPU's onboard sensor supply is dead, replace the CPU or move the sensors to a separate 24 V supply, because that regulator is not field repairable. Prevention in one line: feed the CPU from a real 24 V industrial supply, fuse the field wiring separately, and never share the CPU supply with solenoids, brakes, or anything that makes a voltage spike when it lets go.   Fault two: transistor outputs that smoked   The DC/DC/DC CPUs switch 24 V DC through transistor outputs. Those outputs are rated around three quarters of an amp, and they are not forgiving. The classic killer is a short to ground on the field wire, which is easy to do when the output feeds a solenoid that lives in a wet area or a junction box full of oil. The transistor dies instantly, and the CPU carries on like nothing happened. The symptom is specific. The output LED on the front is lit, the program is running, the output bit is on, and there is no voltage at the terminal. That combination, LED on and terminal dead, is a blown transistor, not a program fault. I have seen people replace a whole CPU and rewire a machine because they chased the program for a day when the answer was a dead output on a $20 relay that should have been there in the first place. The second killer is inductance. Solenoid valves, brake coils, small contactors, all of them kick back a voltage spike when the current is cut. If there is no flyback diode across the coil, those spikes punch through the output transistor a little bit at a time, and one day the output just stops. I have opened panels where every single output on the CPU was dead and the machine had been running for years on luck. The fix is to verify with a meter and then make a decision. Confirm the output terminal has nothing while the LED is lit, check for a short on the field wire, disconnect the load, and see if the output comes back. It will not, because the transistor is gone. Move that load to a spare output if you have one, or replace the CPU, and put the load on an interposing relay before you power up again. Prevention in one line: anything that is not a small, clean DC load gets an interposing relay, and every DC coil gets a flyback diode wired right across its terminals.   Fault three: you cannot talk to the CPU   Every S7-200 job starts with a programming connection, and the comms setup is where old electricians go gray. The CPU speaks PPI on a 9-pin RS-485 port. You talk to it through a programming cable, and the cable is half the battle. The old RS-232 PC/PPI cable, order number 6ES7901-3CB30-0XA0, plugs into a real serial port on the computer. Real serial ports have mostly vanished, which is why that cable now lives in a drawer next to a Windows XP laptop. The USB-PPI cable, order number 6ES7901-3DB30-0XA0, is the modern answer, but it brings its own circus. The genuine Siemens USB cable needs the PC Adapter USB driver installed before Windows will even see it, and Micro/WIN needs to be pointed at the right COM port, which changes every time Windows decides to renumber your USB ports. The cheap clone cables from online marketplaces need their own drivers and a prayer. When Micro/WIN says it cannot find the CPU, work the list in order. Check Device Manager and confirm which COM port the cable actually landed on. Check the PPI parameters in Micro/WIN and set the address to 2 and the baud rate to 9.6 kbps, which is what a virgin CPU expects. Unplug every other USB serial device so Windows stops shuffling port numbers. Power-cycle the CPU with the cable connected. Try the other PPI port if the CPU has two, because a dirty or damaged port 0 will fail while port 1 talks fine. And remember what software you are dealing with. STEP 7 Micro/WIN was last updated around 2010, and it was never happy on modern Windows. In 2026 my programming laptop is an old machine running Windows 7 32-bit, and I have Micro/WIN SP9 in a virtual machine as a backup. If you fight with a 64-bit Windows 10 machine for more than an hour, stop. Get the old laptop out of the truck. You will save your afternoon. Prevention in one line: own one known-good USB-PPI cable, keep it with the laptop that has Micro/WIN already working, and write the COM port number on a sticker so you stop re-discovering it every visit.   Fault four: a comms port that is physically dead   The PPI port is RS-485 on pins 3 and 8, and it is only as tough as the little driver chip behind it. The ways I have seen those chips die: somebody wired the cable while the panel was live, somebody ran the PPI cable in the same conduit as motor cables for fifty feet, somebody dropped 24 V into the port during a wiring mistake, and lightning took a hike down a long outdoor run and stopped at the CPU. The symptom is clean. The machine runs fine, the program is fine, and you simply cannot communicate on that port. If the CPU has a second port, the same cable works perfectly on it, and that confirms the port is dead, not the CPU. The fix is harsh and simple. The port is not field repairable. On a two-port CPU like the 224XP or the 226 you move the HMI or the programming connection to port 1 and keep running. On a single-port CPU, or when both ports are gone, you replace the CPU. That is why I carry a spare 226 in the truck, because it has two ports and it drops into most jobs. Prevention in one line: never plug or unplug the PPI cable with power on the port, keep serial wiring away from power cables, and put a surge suppressor on any PPI run that leaves the building.   Fault five: the program is gone   The phone call goes like this. The machine sat dead for six months while a project stalled. Somebody finally powered it up and the machine did nothing. The plant electrician announces that the battery died and the program is gone, and can we come reprogram it from scratch. Stop right there. Nine times out of ten the program is fine. It is in EEPROM, remember? The EEPROM does not need the battery. What actually happened is that the supercap went flat during those six months, so the retentive data came up empty. Recipe values, counter totals, timer presets that were written to retentive memory, calibration numbers, all of it read as zero at power-up. The program ran, and the machine did nothing sensible, because all its numbers were gone. That looks exactly like a lost program to a man who has been up since five in the morning. First check the RUN LED. If the CPU is scanning, the program is in it. Then connect Micro/WIN and upload the program from the CPU, because the S7-200 will happily hand its program back to you. Save that upload as a .mwp file immediately, because that file is now your archive. Then write the program back to EEPROM so the copy in the CPU matches what you just saved. On the S7-200 the download stores the program block permanently on its own, no battery involved. The cases where the program really is gone are rarer and they all have a story. Someone swapped in a spare CPU that had another machine's program in its EEPROM, and nobody checked. Someone ran a Clear command or held the CPU in a bad state during a download when the power hiccuped. Or someone inserted an EEPROM memory cartridge with an old program, and the CPU booted from the cartridge at power-up, which S7-200s do when a cartridge is present. In those cases the fix is the same upload path if anything is left to grab, and a clean download from your archive if there is not. Prevention in one line: keep the .mwp file and a printed rung listing for every S7-200 you own, and label any spare CPU with the machine and program version that came out of it.   Fault six: the RUN/STOP switch is in the wrong place   This one makes me smile every time because it is so easy. Every S7-200 has a little slide switch behind the front door with three positions: RUN, TERM and STOP. TERM means the CPU lets the programming software start and stop it remotely. STOP means the CPU will not run, period, and it will not run after a power cycle either, because the switch still says STOP. I have been called to plants where the CPU was in STOP, the red SF light was doing whatever it does, and three electricians were convinced the program had been wiped. One of them had even ordered a replacement CPU. I slid the switch from STOP to RUN, the outputs picked up, and the machine started. The look on their faces was worth the drive. Here is the field rule I teach apprentices. If the CPU is in STOP and you did not put it there, ask who was working on the panel last. Someone put it in STOP to do a download or a manual test and never put it back. Switch to RUN and watch. If it drops back to STOP on its own, then you have a real fault, and you read the diagnostics in Micro/WIN instead of guessing. Also learn the LEDs while you are there. RUN green means scanning, STOP amber means stopped, and SF red means the CPU has a fault it wants to tell you about. Solid or flashing SF, plug in and read the error. The S7-200 keeps a small diagnostic buffer and it will tell you exactly what it does not like. Prevention in one line: leave the switch in RUN or TERM when you close the door, and make it a habit to check the switch position before you diagnose anything else.   Fault seven: the TD200 or TD400 text panel went dark   A lot of S7-200 machines talk to an operator through a Siemens text display, the TD200 or the later TD400. They are tough little panels and they outlive everything around them, but they do fail in one confusing way. The panel powers up, shows its logo or nothing, and then reports no communication with the CPU, even though the machine is running fine. The part that trips people up: the TD200 does not hold its own communication settings in a menu. It gets its station address and baud rate from a configuration block that lives in the PLC program. When you download a program to the CPU, that program has to include the TD200 configuration, or the panel has nothing to talk to. I have seen a machine lose its text panel because somebody replaced the program with a version that did not include the panel configuration. The CPU ran fine. The panel sat there dark and confused. Check the simple things first. Is the panel getting 24 V? Is the cable between the panel and the CPU intact, and is it plugged into the right port? If the CPU has one port and it is shared between the panel and the programming connection, remember that the TD200 and TD400 have pass-through connectors so you can daisy-chain the programming cable through the panel. If the plant rewired and put the panel on a dead port, you will see exactly this symptom. Then check the program side. Open the TD200 configuration in Micro/WIN, confirm the address and baud rate match what the CPU expects, and download the blocks again. Power-cycle both the CPU and the panel after the download, because the panel picks up its settings at power-up. Nine times out of ten that brings the screen back to life. Prevention in one line: when you save the archive for a machine with a text panel, make sure the TD configuration block is in the program and note it on the printout, because it is part of the program whether it looks like it or not.   Fault eight: EEPROM and memory errors   The rarest fault on my list, but the scariest one. The SF LED comes on and Micro/WIN reports an EEPROM error or a checksum fault when you try to read the CPU. The program may run, may not run, or may run wrong. What causes it: a power cut in the middle of a download, which is why you never let anybody kill a panel while you are programming. A brownout during the EEPROM write that happens at the end of a download. And the slow killer, a program that writes data to EEPROM constantly. The S7-200 lets you store V memory values permanently with a special write function, and EEPROM has a finite number of write cycles. I have seen a programmer put that write in a routine that ran every scan, and the CPU's EEPROM wore out in a couple of years. The CPU then forgot its program at random times, which is a special kind of nightmare. The fix starts with a full download of all three blocks, program, system block and data block. Sometimes that is enough, because the error was a bad copy in memory and a clean write fixes it. If the CPU throws EEPROM errors again after a clean download, the EEPROM itself is tired, and you replace the CPU. That is also where you discover whether you kept the .mwp archive from fault five. If you did, you are back running in twenty minutes. Prevention in one line: never interrupt a download, never let the plant cut power during programming, and never write to EEPROM from the program more than a handful of times a day, because that memory has a lifetime.   What I keep on the shelf   If you maintain more than two or three S7-200 machines, this is the spare parts list that has paid for itself many times over at my shop. One spare CPU 226, the 6ES7216-2BD23-0XB0 DC/DC/DC version. It covers almost any machine in the family because it has the most I/O, two ports, and it will run a program written for a smaller CPU as long as the I/O maps line up. A CPU 224XP, 6ES7214-2BD23-0XB0, is the second choice if your machines all use the onboard analog channels, because the 226 does not have those. One USB-PPI cable, the genuine 6ES7901-3DB30-0XA0, kept with the programming laptop, and one old RS-232 PC/PPI cable 6ES7901-3CB30-0XA0 in case the USB driver fight gets stupid. A box of small interposing relays and a handful of flyback diodes, because most of the output faults in this article stop happening when those are in the panel. A 24 V DIN-rail supply that you trust, for the day you find fault one. And for the 224 and 226 CPUs, a battery cartridge so a machine that sits powered down keeps its clock and its data. Where does the stock come from in 2026? Siemens has been out of this product for years, so everything you buy is surplus, new-old-stock, or pulled from decommissioned machines. There are brokers all over the world, and the Siemens section at tztechio is the kind of place that tests what it sells instead of just shipping boxes. That matters, because the S7-200 was cloned heavily, and I have seen brand-new-looking CPUs from no-name channels that were anything but genuine. A used genuine CPU from a seller who can tell you the firmware version is usually a safer bet than a shiny clone that costs less and behaves differently when you need it most. Ask the seller to test the ports and the EEPROM before you pay, and ask what firmware it runs. If they cannot answer, buy somewhere else. For wider control-system spares beyond Siemens, tztechio also lists industrial automation stock, which is where I look when a machine mixes brands.   When it is time to move to the S7-1200   I fix S7-200s for a living, so I am the wrong guy to tell you to rip them out. But there is an honest answer about when to migrate, and it is the S7-1200, the machine Siemens built to replace this family. The current second-generation S7-1200 is a fine little PLC and it will run your machine for another twenty years. The hard truth first. You cannot convert the program. STEP 7 Micro/WIN programs do not import into the S7-1200's TIA Portal software. There is no button that does the translation. You retype the logic in a new project, rung by rung, using the old printout and the old .mwp file as your spec. The addressing is different, the system memory is different, the timers behave differently, and the I/O maps to new names. Plan for a rewrite, not a conversion, and budget the time like one. Migrate when the math says so. When the CPU dies and a tested spare is not available at a sane price, that is the moment, because you do not want to re-engineer under breakdown pressure. When the plant is standardizing on TIA Portal and your electricians no longer remember Micro/WIN, that is another good reason, because in 2026 the old software knowledge is retiring. When the machine needs Ethernet, remote access, or a modern HMI that does not speak PPI, the S7-200 simply cannot do it, and that is a real limit, not a preference. When you do migrate, do it like a field job. Build the new panel with the S7-1200 and prove the logic on the bench against the old printout. Then take the machine down once, on a planned outage, and swap. Keep the old CPU on the shelf until the new machine has run for a month, because the old one is your rollback plan. I have done this swap on packaging lines, on pump skids, on gate controls, and the recipe never changes. Prove it, swap it, watch it, and only then let the old brick retire.   Quick reference: the faults at a glance   Here is the whole article on one page for the day you are standing in front of a dead machine with a phone in your hand. Fault | What you will see | Usual cause | Fix that works Dead 24 V supply | Random outputs, STOP, or dead inputs | External supply sagged or died | Measure L+ and M under load, fix the supply Blown transistor output | Output LED lit, no voltage at terminal | Short to ground, no interposing relay | Meter confirms it, move load to a relay No programming comms | Micro/WIN cannot find the CPU | COM port, driver, or cable issue | Work the port list, try 9.6 kbps, try port 1 Physically dead port | Machine runs, one port silent | Wiring live, ground loop, surge | Use the second port or replace the CPU Program looks lost | Machine dead after long power-down | Flat supercap, retentive data zeroed | Upload from the CPU, save .mwp, download clean CPU stuck in STOP | RUN LED off, machine idle | Switch left in STOP | Slide to RUN, then check diagnostics TD200 or TD400 dark | Panel on, no communication | Missing TD config block, bad cable | Check power, check config, download blocks EEPROM error | SF LED, checksum fault | Power cut mid-download, worn EEPROM | Full download, replace CPU if it repeats That table is the short version of twenty years of callouts. Print it, tape it inside the panel door, and the next electrician who opens that box will thank you. The S7-200 is old, discontinued, and officially forgotten by its maker. None of that matters to the machines still running on it in 2026, and none of it matters to the men who keep those machines running. Learn the faults, carry the spares, keep the archives, and this PLC will keep paying your bills for another decade. When the day finally comes that a machine has to move to the S7-1200, you will do it on your terms, in daylight, with a tested program and a rollback plan. That is how old iron gets retired properly. One panel at a time, on purpose, not in a panic at two in the morning. URL Slug: siemens-s7-200-field-guide ------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).i  
  • The SIMATIC S5 Is Still Running Your Plant: A 6ES5 Field Guide for 2026
    The SIMATIC S5 Is Still Running Your Plant: A 6ES5 Field Guide for 2026 Aug 11, 2026
    The phone rang at 2:37 in the morning. I knew it was a plant before I picked up. Nobody calls at 2:37 in the morning to talk about the weather. "It's Karim. The dairy. Mixer line three stopped at 2:10. The CPU light is out." Karim runs maintenance at a dairy that fills yogurt cups for half the Gulf states. I had stood in his electrical room six months before that call. I remembered the cabinet: a Siemens SIMATIC S5-115U, a row of brown and beige modules, a bank of green LEDs, and a small battery holder clipped to the CPU card. That machine was delivered in 1988. It had been filling cups before Karim was born. "Did you change the battery, Karim?" Silence. Then: "What battery?" That is how almost every S5 emergency starts. Not with a blown module. Not with a shorted output. With a battery. The 6ES5980-0AA11 is a 3.6 volt lithium cell about the size of a D battery. It keeps the CPU's RAM alive when the mains power drops. When it dies, the RAM goes blank, and the CPU wakes up with no program to run. The machine stops, the alarm sounds, and somebody calls somebody like me at 2:37 in the morning. Karim got lucky. His predecessor had left a disk backup and an old laptop with STEP 5 installed, so we had the line running by 5:40. The six o'clock shipping deadline held by twenty minutes. Not every plant is that lucky. In thirty years of working on these machines, I have watched the same scene play out in cement plants, bottling lines, steel mills, and water treatment stations on three continents. The S5 refuses to die, and the people who keep it alive make the same mistake: they ignore the battery until the battery forces the issue. Consider this the conversation I wish I could have with every maintenance team that still carries an S5: why the machine is still there, what actually breaks, where to find 6ES5 spares in 2026, and when to start walking toward S7.   Why a 1979 design is still on shift in 2026   Siemens introduced the SIMATIC S5 in 1979, replacing the S3 series. The early S5-110A and the big S5-150U came first, and then the family grew to cover the whole market. The S5 was built around one programming language, STEP 5, and that decision is a big reason the family survived so long. One language, three ways to write it: statement list (STL), ladder (LAD), and function plan (FUP). One family of programmers, from the PG675 through the PG7xx series and later STEP 5 on a PC. Learn one S5, and you could walk up to any of them. The range covered everything a factory needed. Small machines got the compact S5-90U and S5-95U. Small modular systems got the S5-100U. The middle of the market, which is where most factories live, got the S5-115U. Big continuous processes got the S5-135U and the S5-155U, and the redundant S5-155H ran the applications where stopping was not an option. The S5-115U became the workhorse. Its CPUs, from the small 941 up to the 945 with floating point math, sat in a rack with a power supply, interface modules, and I/O cards, and they ran packaging lines, conveyors, pumps, presses, and mixers for decades. I have opened cabinets in Rotterdam, Cairo, Houston, and Dubai and found the same brown modules inside. The S5-115U is the most widespread PLC Siemens ever built for the mid-range, and the installed base never really went away. Plants did not replace them because they worked. They still work. That is the uncomfortable truth of 2026: tens of thousands of S5 systems are running production right now, most of them S5-115U, some of them running 24 hours a day, seven days a week, for thirty or forty years. The design was overbuilt. The documentation culture around it was strong. The machines around it, the motors, gearboxes, and valves, are older than most of the engineers who maintain them. Nobody replaces a working line to fix a problem it does not have.   The family tree, in one breath   If you walk into a plant and see an S5, here is what you are looking at. The S5-90U and S5-95U are the compact units, the 95U with more memory and a few built-in functions. They live inside packaging machines, labelers, and small presses. The S5-100U is the small modular system, a step up in expandability. The S5-115U is the mid-range workhorse with the huge installed base, the one you will meet nine times out of ten. The S5-135U is a multiprocessor system for bigger machines, and the S5-155U and S5-155H sit at the top, running steel mills, chemical plants, and power station auxiliaries, the H version with redundant CPUs for the applications that cannot stop. Every one of them speaks STEP 5. That was the genius of the family. One language from the smallest 90U to the biggest 155H. A maintenance man who learned STEP 5 in 1985 could still read a program in 2005, and the same skill works today. I learned on a 115U in 1991. An old paper mill, a CPU 944, and a PG685 programmer the size of a suitcase. The senior electrician, a man named Bert, showed me how to pull the EPROM submodule out of the CPU, stick it in the programmer, and read the program. He told me something I have never forgotten: "The program is worth more than the machine. Guard the program." Thirty years later, that is still the first thing I check on any S5 site. Do you have the program? Where is it? On EPROM? On disk? On a printout in a drawer?   What actually fails after decades of service   The S5 hardware is tough. The failure list is short, and it has not changed in thirty years. Everything that dies on an S5 dies in one of four places: the battery, the power supply, the memory, or the I/O.   The battery, always the battery   The 6ES5980-0AA11 lithium cell is the number one cause of S5 downtime in the world. It is a consumable, like a filter or a bearing, but nobody treats it like one. The cell costs a few dollars. The downtime it causes, when the program vanishes from RAM, costs thousands. I have a rule I tell every customer: change the battery every two to three years, on a schedule, with a sticker on the cabinet door. Buy two spares and store them in the cabinet. A battery is not a spare part you order after the failure. It is a spare part you install before the failure. The first sign is the battery lamp on the CPU front, but that lamp only comes on when the voltage is already low. Check it the honest way: measure the cell with a multimeter, under load if you can, and replace it if it reads below about 3.2 volts. And never change the battery with the power off, because that is the moment the RAM forgets everything. Change it with the system running, or with the CPU powered up and the program safely in EPROM. If the worst happens and the RAM is blank, all is not lost. If you kept the program on an EPROM submodule, you can copy it back into RAM from the programmer. If you kept a disk backup, you can load it. If you kept only a printout, you get to retype it, line by line, and I have done that twice in my life and I hope never to do it again.   Power supplies: 6ES5 951 and 6ES5 955   The second most common failure is the power supply. The S5-115U uses the 6ES5 951-7LD21 for AC mains and the 6ES5 955-7LD21 for 24V DC plants. These modules are full of electrolytic capacitors, and capacitors age whether the machine runs or not. After twenty-five years, the 5V rail starts to sag. The PLC does strange things: spurious faults, random stops, outputs that drop for no reason. Then one day the module gives up. I remember a cement plant in Upper Egypt where the line stopped twice a week for months. Every time, the same fault, a mysterious CPU stop with no error. They changed the CPU, the battery, the memory. I walked in, looked at the 6ES5 951, and measured 4.6 volts on the 5V rail. The capacitors were dried out. We swapped the power supply and the mystery never came back. The tell is the little voltage lamp on the front of the module. If it looks dim, or if the 5V rail measures under 4.9 volts, replace the module before it replaces your night's sleep. Power supply modules are one of the most traded 6ES5 parts today, both used and NOS, because every S5 owner eventually needs one.   EPROM memory submodules   The program often lives on an EPROM submodule, the 6ES5 375 series and similar, plugged into the CPU. These are remarkably reliable. They hold their data for decades. But they are not immortal, and they have one weakness: the UV window. Ultraviolet light erases EPROMs with a quartz window. Sunlight is ultraviolet light. I have seen a spare EPROM stored on a windowsill for six years, and when the plant finally needed it, it was blank. I have also seen a lightning strike take out an EPROM through the field wiring, which is why the program backup should live in more than one place. My rule: keep the master program on a PC, keep a copy on EPROM or EEPROM inside the cabinet, and keep a printout in the office. Three copies. One of them will survive whatever happens.   Digital I/O: 6ES5 421, 422, 441, 451   The I/O cards are the soldiers of the system. They take the punishment from the field, and they die the most interesting deaths. The 6ES5 421 and 6ES5 422 digital input cards, 16 and 32 channels, fail when a surge comes in on the field wiring. A lightning storm, a shorted solenoid, a crane touching a power line, and the optocouplers inside give up. The 6ES5 441 and 6ES5 451 digital output cards fail when a load shorts or when somebody wires 220V into a 24V output. I have seen output cards returned with actual scorch marks on the plastic. The good news: I/O cards are the easiest 6ES5 modules to replace, and they are still widely available as used and new old stock. The bad news: the field wiring around them is often the real problem, and a new card on old wiring is a new card waiting to die. Check the wiring first. Then swap the card. The other quiet killer is the interface modules, the IM 305, IM 306, and IM 308 that connect the racks. They fail rarely, but when a rack goes dark, everyone blames the CPU first. Reseat the IM modules, clean the backplane contacts, and check the flat cables before you order anything.   The S5 troubleshooting table   Keep this table on the cabinet door. It covers the faults I have seen most often in the field, and the part numbers you will actually need. Fault | Likely cause | Fix | Spare part number CPU dead, no LEDs, program gone | Backup battery flat, RAM lost the program | Replace battery, reload program from EPROM or PC backup | 6ES5980-0AA11 Battery lamp lit on CPU front | Cell voltage low | Measure under load, replace cell with power on | 6ES5980-0AA11 No 5V rail, power supply LED dark | Failed 6ES5 951/955, aged capacitors, blown fuse | Replace the power supply module | 6ES5 951-7LD21 (AC) or 6ES5 955-7LD21 (DC) Input channel stuck on or off | Surge damage, failed optocoupler, bad field connection | Check wiring, swap input card | 6ES5 421-7LA11 or 6ES5 422-7LA11 Output will not switch, fuse keeps blowing | Shorted load, failed transistor or triac | Clear the short, replace output card | 6ES5 441-7AA11 or 6ES5 451-7LA11 Spurious CPU stops, corrupt program, wrong cycle times | Aged EPROM or EEPROM submodule | Reload program, replace submodule | 6ES5 375-0LC21 (EPROM) Expansion rack dark, IM error LEDs on | Loose or failed IM module, corroded backplane | Reseat, clean contacts, replace interface module | 6ES5 305, 6ES5 306, or 6ES5 308   Where to find 6ES5 spares in 2026   The honest answer to the question I get every week: yes, you can still buy 6ES5 modules in 2026, and the market is healthier than most people think. Siemens officially discontinued the S5 family long ago. Production stopped with it, and the factory repair service is gone. That sounds like a dead end, but the market filled the gap years ago. Two kinds of stock keep the S5 world alive. New old stock (NOS) is the treasure: modules that sat in warehouses for decades, never installed, still in the original packaging. A surprising amount of 6ES5 stock survived, because distributors and OEMs bought deep when Siemens announced the end of production. NOS power supplies, CPUs, and I/O cards still change hands every month. Used modules come from decommissioned plants. When a factory finally migrates to S7, the entire S5 cabinet often goes to a dealer who tests the modules and resells them. A tested, working used module with a warranty is a perfectly good spare for a machine that will run another ten years. Beyond specialist dealers, used 6ES5 modules also show up on general marketplaces, but there the risk is the test report: an untested module is a lottery ticket, and a module that was pulled from a flood-damaged cabinet is worse than no module at all. At tztechio.com we keep a working stock of exactly the modules that fail, the batteries, power supplies, memory submodules, and I/O cards, and we test every used module before it goes on the shelf. Before you buy any used or NOS module, check three things. First, the order number on the label, the full MLFB like 6ES5 421-7LA11, because a one-digit difference can mean a different voltage or polarity. Second, the version number, because later versions of the same module usually carry fixes. Third, ask whether the module has been tested and whether it carries a warranty. A dealer who tests modules and backs them is worth more than the module itself. Prices follow the laws of supply and demand, and 6ES5 demand is still real. Batteries and power supplies are the highest turnover items. Some modules, the rare 155U CPUs and the redundant 155H parts, have gone up in value over the years. The market is mature, and it will be there for a while, because the installed base is still enormous.   The migration path: S5 to S7   The S5 will not run forever. The question is not whether to migrate, but when, and how to do it without a fire drill. The honest advice from someone who has done this many times: do not migrate a working line just because the PLC is old. The machine works. The spares are available. The program is understood. That combination is worth real money. Plan the migration, buy the spares, and migrate when one of these things happens: the spares start getting hard to find, the machine must talk to a modern MES or ERP system, the last person who understands the program retires, or the S5 fails in a way that cannot be repaired. When the time comes, the path leads to the S7-300 for mid-range machines and the S7-400 for the big ones. The two families are cousins. STEP 7 speaks a language close to STEP 5, and Siemens built a conversion tool into STEP 7 that translates S5 programs to S7. The tool does the heavy lifting, and then a human does the real work. Because the translation is never clean. S5 timers, flags, data blocks, and the S5-115U's addressing all have S7 equivalents, but they do not line up one for one. A good conversion project is a bench test first: convert, simulate, test every input and output against the old printout, then cut over on a planned weekend. I have seen a well-prepared team convert a whole bottling line in one weekend. I have also seen a rushed team convert a single pump station in a week. The difference was preparation, not the PLC. There is also a middle path. If the S5 itself is healthy but the plant needs modern communication, gateways can put an S5 on PROFIBUS or industrial Ethernet and let it talk to an S7 or a modern SCADA. That buys years of life without touching the control logic. It is a real option, and it is often the smart one. Whichever path you take, the first step is the same as Bert taught me in 1991: guard the program. Before anything else, make sure the S5 program is backed up in at least two places, because a conversion starts from a backup, not from a prayer. When you are ready to look at what comes next, our PLC controllers page covers the S7 side of the story, and we can help you match the right controller to the machine you are actually running.   The S5 owner's checklist   If you carry an S5, this is the short list I give every customer, the one I wish Karim had been given in 2019: 1. Change the 6ES5980-0AA11 battery every two to three years, on a schedule, with the power on. Keep two spares in the cabinet. 2. Back up the program in three places: PC, EPROM, printout. Verify the backup actually loads, once a year. 3. Stock one spare power supply, 6ES5 951 or 6ES5 955 depending on your plant, and one spare of each critical I/O card. 4. Keep the cabinet clean and cool. Dust and heat kill capacitors and connectors. Check the cabinet filter, and clean the backplane contacts when you are in there. 5. Label everything. When the S5 finally leaves the building, the next engineer will bless your labels. 6. Buy the spares before you need them. The module you need in an emergency is the one nobody stocked. We carry the full range of industrial automation spares, and the S5 section of our Siemens catalog is built around exactly these failure points.   Questions maintenance engineers ask about the S5   Is the SIMATIC S5 still supported by Siemens? Officially, no. Siemens discontinued the S5 family and closed the repair service years ago. Unofficially, the market never stopped supporting it. Used and NOS modules, third-party test and repair services, and experienced engineers keep the installed base alive. Support for the S5 in 2026 means the spares market, not the factory. Can I still buy 6ES5 modules in 2026? Yes. Batteries, power supplies, CPUs, memory submodules, and I/O cards are all still traded, as used modules and as new old stock. Some 6ES5 parts, especially the power supplies and I/O cards, are available within days. The rare 155U and 155H parts take longer, which is exactly why you should stock them before you need them. How do I check the S5 backup battery? Measure the 6ES5980-0AA11 cell with a multimeter, ideally under load. A healthy cell reads above 3.2 volts. Below that, replace it, with the system powered up so the RAM never loses the program. The battery lamp on the CPU is a late warning. The multimeter is the early warning. How long does the battery last? Two to five years is the practical range, depending on temperature and how often the plant loses power. The cell drains faster in hot cabinets. Change it on a two to three year schedule and you will never have to think about it again. Can I program an S5 with a modern PC? Yes, with patience. STEP 5 version 7.2 runs on older Windows systems, and many engineers run it inside a virtual machine with a CP5611 card on the plant network. It is museum software, but it works, and it is still the only official way to read and edit an S5 program. If your only programmer is a retired engineer with a PG720 in his garage, make friends with him now. Do I have to migrate to S7? No. If the machine runs, the spares are available, and the program is safe, keeping the S5 running is a legitimate strategy. Migrate when the risk outweighs the cost, not because a salesman says the technology is old. The S5 is old. Old is not the same as broken. Somewhere right now, an S5-115U is counting yogurt cups, or bottles, or kilowatt-hours, and it will still be counting tomorrow. These machines were built to outlast the people who installed them, and most of them have. They ask for very little. A battery every couple of years. A spare power supply on the shelf. A program that is backed up in three places. Give them that, and they will keep running while you plan the future at your own pace. That is the deal I have made with every S5 I have ever met. Change the battery. Guard the program. Call us when you need the parts. ------------------------------------------------------------------------------------------ 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).  
  • Siemens S7-400H redundant system troubleshooting
    Siemens S7-400H redundant system troubleshooting Jul 30, 2026
      I've been keeping S7-400H systems running for almost twenty years now. These redundant racks were built to never stop, but they stop all the time. The CPUs are almost always fine. Sync modules, power supplies, fiber links are what fail. The H system itself is solid. The problem is everything else gets old and tired, and when redundancy goes south, you're running on one CPU with no backup. I work at a shop that's been in the Siemens PLC game since the S5 days. The S7-400H came out in 1996 and plants are still running them. This article covers the faults I've fixed on live systems. Real numbers, real fixes, no theory.   Lost redundancy and the yellow LED   You walk up to the panel and one CPU shows a yellow IFM1F or REDF LED. The other CPU is running solo. This is the most common call I get. First thing: check the sync modules. S7-400H uses two sync modules per CPU, connected through fiber optic cables. Part numbers are 6ES7 960-1AA04 for the standard fiber or 6ES7 960-1AB04 for the extended range. I've seen more sync module failures than CPU failures by a long shot. Look at the SYNC LED on each sync module. If it's off or blinking when it should be solid, that module is dead or dying. Swap it. Don't bother testing it. Then check the fiber cables. These things get bent, pinched in cabinet doors, chewed by rodents. Hold one end up to a bright light. If you see any light leak through the jacket, replace it. Use a fiber power meter if you have one. You need at least -20 dBm at the receiver. Below -25 dBm and you'll get intermittent sync loss, usually right when production is at max. Re-terminate the fiber connectors if the ends are dirty. Use a one-click cleaner, not your shirt. I've fixed more broken sync modules with a $12 cleaning pen than with a $600 replacement part. If sync modules and cables check out, force a redundancy re-establish. Put the CPU in STOP, then back to RUN. In STEP 7, go to PLC > Diagnostic/Setting > Operating Mode. The system should re-sync. If it doesn't, you're looking at a hardware fault on the backplane or the CPU itself.   Redundant power supply problems   The PS 407 power supplies (6ES7 407-0KA02-0AA0 or similar) are workhorses, but they have a weak spot: the backup battery monitoring circuit. Common scenario: one supply shows a BATT LED on. The system keeps running, nobody cares, and three months later the other supply fails too. Now you're down. I've seen it a hundred times. What I do is pull the suspected bad supply and check output voltage at the terminals on the back. You should see 24V DC within 2%. Anything below 23V or above 25V means the regulation circuit is drifting. Replace it. Don't adjust it. There's no trim pot on these. The hidden one: the power supply might be fine, but the 24V DC input to the rack is sagging. Check the input terminals on the PS 407. If input drops below 20.4V (the S7-400's undervoltage threshold), the supply will flag a fault. This happens more than you'd think. Bad circuit breakers, loose terminals, undersized wire. Redundancy module failure is another issue. If you have the redundancy module (6ES7 407-0RA00-0AA0) between two power supplies, that thing fails too. When it goes, one supply looks dead to the rack even though it's outputting voltage. Bypass the redundancy module temporarily. Jumper the outputs to confirm. If the rack comes back, replace the module.   IM 460/461 interface module faults   The IM 460-1 (6ES7 460-1BA00-0AA0) in the central rack and IM 461-1 (6ES7 461-1BA00-0AA0) in the expansion rack are another weak point in H systems. These are the interface modules that connect the two racks of a redundant pair. The symptom: one CPU reports Ext. DP Fault or BUS2Fault but the other CPU is fine. The redundant pair can't sync because the expansion rack communication is broken. Quick test: swap the IM 460-1 between the two racks. If the fault moves with the module, it's bad. If it stays in the same slot, the problem is the backplane or the cable between racks. Cable problems: the connecting cables (6ES7 468-xx) have those big rectangular connectors. I've had the latch break off, the cable partially pull out, and the system sees intermittent faults for weeks before someone catches it. Push the connector in firmly. If it clicks, good. If it doesn't click, replace the cable end.   CPU memory card corruption   S7-400H CPUs use memory cards. MMC or earlier RAM cards. The battery kills these cards when it dies and the CPU powers down. The redundant system will start up but one CPU won't go into RUN because it can't load its operating system. Pull the memory card and put it in a reader connected to a PG/PC. Try to read it. If Windows asks you to format it, the card is dead. If you can read it, back up the project, reformat the card, and rewrite it. The practical fix: always keep two programmed spare memory cards for each CPU type in your cabinet. When this happens (and it will), you swap the card in thirty seconds instead of spending an hour rebuilding it. If both CPUs lost their cards at the same time (usually from a total power loss with dead backup batteries), you'll need to download the project fresh. The RAM-based clocks can drift during this too, so set the time on both CPUs after loading.   Ext. DP slave faults in redundant mode   This one drives me nuts. The redundant system is running fine, but a DP slave (maybe an ET 200M or a remote I/O rack) shows up as faulted on one channel but not the other. Root cause: the DP master on one CPU lost the slave, re-established it, and now the slave is assigned to the wrong master. The two CPUs don't agree on who's driving that slave. Fix in STEP 7: go to the hardware config and check the Redundancy properties for that DP slave. Make sure it's set to Redundant DP Master. If it's set to a specific master slot, change it. Then power-cycle the slave device. After any DP slave replacement in a redundant system, you have to re-assign the slave to both masters. The Slave Replacement procedure in the manual is: disconnect slave from power, replace, power back on, then use HW Config > PLC > Download to Module for the DP slave. If you don't do both masters, the slave will work for one CPU and fault for the other.   When to replace the CPU itself   CPU replacement (414H, 417H, etc.) is rare but it happens. Here's when I pull the trigger: · The CPU goes into STOP with an internal error code that doesn't clear after a memory reset · Multiple I/O modules on the same CPU show no connection but the backplane is fine · The INTF LED stays on permanently even after a fresh OB1 download · You see Distributed I/Os: station failure on one CPU but the other CPU communicates with the same slaves fine Swapping a CPU in an H system: put the good CPU solo, pull the bad CPU, install the new one, set the mode selector to MRES and hold for nine seconds (until the STOP LED stops blinking and stays solid), then set to RUN. The good CPU will download the system data to the new CPU automatically. Let it finish. Don't interrupt this. It takes two to five minutes depending on the program size. The mistake I see: guys swap the CPU and don't match the firmware version. If the new CPU has a different firmware than the existing one, redundancy won't establish. Always check the 6ES7 400 firmware version in the diagnostics buffer before ordering a replacement.   Sync module part number matching   One thing that'll cost you hours: sync module part numbers must match on both CPUs. If rack 0 has 6ES7 960-1AA04 and rack 1 has 6ES7 960-1AB04, the system won't sync. I don't care if the documentation says they're compatible. In the field, they aren't. Keep matched sets. Same thing with the fiber lengths. If one cable is a 1-meter and the other is a 10-meter, the signal timing difference can cause sync loss on long scan cycles. Use the same length on both links.   Practical diagnostic steps summary   When I walk into a plant with a faulted H system, this is my order: 1. Look at the LEDs on both CPUs. Note every LED state. 2. Read the diagnostics buffer on the solo CPU (the one still in RUN). 3. Read the diagnostics buffer on the faulted CPU. 4. Check sync module LEDs on both racks. 5. Check power supply LEDs and battery LEDs. 6. Listen to the power supplies for the fan. If one fan is dead, swap that supply now. The diagnostics buffer tells you 90% of what you need. Don't guess. Read it. Most S7-400H problems are not the CPUs. Sync modules, power supplies, IM modules, and fiber cables fail long before the main PLC does. Keep spares of the expensive stuff (the sync modules and the IM modules), because waiting three days for a replacement 6ES7 960-1AA04 is going to cost more than stocking it. And check those batteries on every PM schedule. A dead backup battery turns a two-minute power cycle into a four-hour rebuild. ------------------------------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).
  • ABB AC500 PLC Troubleshooting: Answers to the Most Common Field Problems
    ABB AC500 PLC Troubleshooting: Answers to the Most Common Field Problems Jul 27, 2026
      The ABB AC500 platform, PM5xx, PM58x, and PM59x series, is used across water treatment plants, building automation systems, and process lines in Europe and the Middle East. Engineers on the ground run into the same predictable faults.   Why is my AC500 CPU not starting up?    A dead CPU on power up comes down to four things. Power supply first. The TA521 series supply modules need a clean 24 VDC input. Check the green LED on the front of the supply module. If it is off, you have no DC input, the input voltage is below 19.2 V, or the supply module itself has failed. Measure right at the terminals with a multimeter. Do not trust the panel indicator light. Bootloader corruption. Less common. It happens on PM582 CPUs after a failed firmware update or power loss during the update. The CPU power LED turns on but nothing else happens. Reload firmware via the SD card slot using Automation Builder. If that fails, the CPU needs a bootloader reflash from ABB. Memory card issues. On the PM591 and PM592, use a FAT32 formatted SD card with a valid firmware image. A card from another PLC or a corrupted card will prevent boot entirely. Remove the card and try booting without it. If the CPU starts, the card is the problem. RUN/STOP switch position. Sounds obvious, but we have walked engineers through this one more than once. If the switch is in STOP mode, the CPU powers on but does not execute the program. Move it to RUN and toggle the power cycle. --- What do the LED flash patterns mean on a PM582?   The PM582 status LED tells you exactly what is wrong if you know the flash code: LED Pattern | Meaning | Action Solid green | Running normally | Nothing Flashing green (slow) | STOP mode | Check RUN/STOP switch or program state Flashing red, 2 flashes then pause | Hardware fault | CPU needs replacement Flashing red, 3 flashes then pause | Bus error | Check the TA523 backplane module and I/O bus connections Flashing red, 4 flashes then pause | Program fault, watchdog timeout | Review cycle time and program logic Solid red | Fatal fault | CPU is likely dead, replace it Three flashes (bus error) is the one that tricks people. Everyone assumes the CPU is bad, but it is almost always the backplane or a loose I/O module. Reseat the TA523 backplane module and all connected I/O modules, then power cycle. If the three-flash pattern persists, replace the TA523 first. It is cheaper than a CPU. Four flashes (program fault) means the watchdog tripped. Go into Automation Builder and check the task configuration. Your cycle time exceeds the configured watchdog limit. Increase the watchdog time or optimize your code. Look for infinite loops in ST, forgotten jump labels in LADDER, or SFC steps that never complete. --- Why can't I connect via Ethernet to my AC500?   Ethernet connection issues are the second most common headache. Wrong IP address. The default IP on the PM5xx series is 192.168.0.10. If someone changed it or your laptop is on a different subnet, you will not connect. Hold the CPU in STOP, connect directly with a crossover cable (most modern NICs auto-MDIX, but not all), and scan the network with Automation Builder's network discovery tool. Subnet mismatch. Your laptop might be on 192.168.1.x while the PLC is on 192.168.0.x. Set your laptop to a static IP in the same range: 192.168.0.100 with subnet 255.255.255.0. Firewall blocking ports. Automation Builder uses TCP ports 6681 and 6682 for communication. Windows Defender Firewall or corporate security software often blocks these. Add an inbound rule to allow them. Also check that the PLC is not behind a managed switch with port security enabled. Physical layer damage. Industrial environments eat RJ45 connectors. Vibration, moisture, oil mist -- all of it degrades Ethernet cables. Try a known good cable. If the link LED on the CPU Ethernet port does not light up when you plug in, swap the cable. If it still does not light, the port may be fried. Use the second Ethernet port if your CPU has one, or add a CM574 Ethernet module. --- My analog input readings are all over the place -- what's wrong?   Drifting or wildly fluctuating analog values on a TA521-AI4 or TA522-AI8 module are wiring or configuration issues, not a bad module. 4-20 mA loop problems. The most common cause is a broken wire in the loop. Check continuity from the transmitter to the AI module. Next, verify loop power. If the transmitter is loop powered, the 24 V supply must be present and stable. A dropout of even 50 ms causes a spike in the reading. Use a precision resistor (250 ohm) across the input terminals and measure voltage. 1-5 VDC across the resistor equals a healthy 4-20 mA loop. Ground loops. When the transmitter and the PLC are on different power supplies or grounding points, ground loops inject noise into the signal. Use isolated AI modules or install a signal isolator between the transmitter and the PLC input. Wrong scaling in Automation Builder. Every analog module needs the correct scaling parameters. If you configured a 4-20 mA input as 0-10 V or set the wrong engineering units range (for example, 0-100 PSI instead of 0-250 PSI), the readings will look wrong but the module is fine. Check the module configuration in Automation Builder under the I/O mapping tab. Filter settings. The AC500 AI modules have configurable digital filters. If the filter time constant is set too low, you will see electrical noise. Too high, and you will miss real process changes. Start with 50 ms and adjust from there. Common mode voltage. On the TA521-AI4, the maximum common mode voltage is 30 VDC between any input and AGND. If your transmitter is referenced to a different ground, you can exceed this and get erratic readings. Tie all analog commons together at one point. --- My program uploads but the PLC goes to STOP immediately   The program loads fine, then the CPU drops to STOP. Missing hardware configuration. Your program references I/O modules that are not physically present, or the backplane configuration in Automation Builder does not match what is on the rail. Open the hardware configuration and run a compare against the actual hardware. If you swapped a TA521 for a TA522 or moved modules to different slots, the configuration is invalid. Task overflow / watchdog timeout. The program compiles and loads, but the cycle time exceeds the task watchdog when it executes. This happens when you add a heavy function block, like a PID loop with a fast cycle time, that did not exist in the previous program. Check the task configuration and increase the watchdog time, or optimize the offending code block. Division by zero or unhandled exception. ST and LADDER code will crash the CPU if you hit a division by zero, an invalid pointer, or an array index out of bounds. There is no automatic exception handler. The CPU goes to STOP. Add bounds checking before math operations. In ST, check the divisor is not zero before dividing. In LADDER, use compare blocks before math functions. Forcing outputs in STOP. If you had digital outputs forced online and you upload a new program, the forcing state can conflict with the new logic. Clear all forces before uploading. In Automation Builder, go to the force view and remove all forces, then download the program. --- Where can I still get spare AC500 modules?   The AC500 platform has been through several lifecycle phases. Some modules are still active; others are discontinued. ABB direct is the first call for current models (PM591, PM592, CM574) but lead times can run 8-16 weeks for older models. The PM571, PM582, CM571, and several TA521 series variants are discontinued or end of life. Automation parts distributors like Rexel, Sonepar, and specialized industrial automation houses still carry NOS (new old stock) inventory. Prices vary widely. Check multiple sources. Specialty suppliers like tztechio.com carry tested used and new surplus AC500 modules, especially the harder to find models like PM582 and CM571. Discontinued modules you will struggle to find new: · PM571 · PM582 · CM571 · TA521 series (several variants, but the TA521-ETH and TA521-AI4 are still more available than others) · Older backplane modules If you are designing a new system or replacing a failed CPU, spec a PM591 or PM592 instead of a PM582. They are current production and have better availability. --- Can I use an AC500 with older ABB drives?   Yes. The AC500 communicates with older ABB drives over serial Modbus RTU. Modbus RTU via CM572. The CM572 serial communication module gives you RS-232 and RS-485 ports. Configure it as Modbus master in Automation Builder. Wire the RS-485 terminals (A+/B-) to the drive's Modbus port. Pay attention to termination resistors. Enable them only at the two physical ends of the bus. ACS350 and ACS355 drives support Modbus RTU out of the box. The drive parameter group 53 (Modbus configuration) sets the station ID, baud rate, and parity. Match these to the CM572 configuration. Common settings: 19200 baud, 8 data bits, even parity, 1 stop bit. DriveAP library. ABB provides the DriveAP function block library for Automation Builder. It handles Modbus communication to ABB drives without writing raw Modbus function codes. Drop in a DriveAP block, configure the drive ID, and read/write parameters by index. ACS580 and ACS880 drives also work over Modbus RTU, but they also support Ethernet-based fieldbuses if you have a CM574 or the CPU's built in Ethernet port. For new installations, use Modbus TCP instead of RTU. It is faster, easier to troubleshoot, and has fewer wiring issues. --- Summary   Most AC500 faults fall into a handful of categories: power issues, configuration mismatches, wiring problems, and module lifecycle. Keep a spare TA523 backplane on the shelf. It is the most common failure point after the power supply. When in doubt, let the CPU's LED flash code tell you where to look first. For more on ABB automation products, check out our guides on ABB PLC platforms, PLC fundamentals, variable frequency drives, and industrial automation systems. ------------------------------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).
  • Allen-Bradley PLC-5: End-of-Life Guide, Replacement Options & Where to Find Spare Parts
    Allen-Bradley PLC-5: End-of-Life Guide, Replacement Options & Where to Find Spare Parts Jul 22, 2026
      The phone rang at 11 PM on a Tuesday. Ammonia refrigeration skid at a cold storage facility — the whole system dropped into fail-safe, product temperature climbing. The PLC-5 had a solid red PROC LED and no amount of power cycling brought it back. I swapped in a spare 1785-L80B, reloaded the program from a floppy disk, and had the refrigeration back online before the first pallet of frozen meat started to soften. That CPU ran continuously for fourteen years. It chose that night to die. The PLC-5 family was discontinued years ago. Last-order dates passed. But the installed base is enormous, and these systems do not fail on a schedule that suits your budget cycle.   Why Plants Still Run PLC-5 Systems   Replacing a working control system costs six figures and requires a plant shutdown. A PLC-5 running a batch reactor that has been making the same product since 1997 — the program is debugged, the operators know it, and the production manager has no appetite for a migration project that risks weeks of commissioning delays. The 1771 I/O rack and 1785 processors were built when Rockwell over-engineered everything. Gold-plated backplane connectors. Heavy-gauge steel chassis. A 1771-PS7 from 1992 will still regulate within spec if the capacitors have not dried out. I have seen PLC-5 systems running steel mill table drives, chemical batch sequencing, pipeline valve control, and half the automotive transfer lines built in the 1990s. The capital request for a migration sits in a drawer, waiting for a catastrophic failure or a budget year that never comes.   Common Failure Modes   After twenty-plus years in the field, here is what actually fails — not what the manual says can theoretically fail.   Power Supply Failures (1771-PS7)   The 1771-PS7 provides 5V and 24V DC to the backplane. The electrolytic capacitors inside have a finite life — roughly seven to ten years in a ventilated panel. In a sealed cabinet running at 50°C ambient, those caps drift out of spec in five years. Symptoms of a failing PS7: · Intermittent rack faults clearing on power cycle · Flashing or dim PWR LED · Unexplained I/O communication errors on specific slots · 5V rail measuring below 4.75V on a multimeter When the PS7 fails completely, the entire rack goes dark. I carry a spare 1771-PS7 in my truck. The PS7 has a distinct failure signature depending on line voltage. On 120V/60Hz (North America), rectifier diodes tend to fail before the caps. On 230V/50Hz (Europe, Middle East), input filter capacitors fail first — the higher RMS voltage stresses the dielectric harder. Stock with CE and UL certification requirements in mind.   Battery-Backed RAM Loss   The 1785 processors use a 3.6V lithium battery (1770-XY) to maintain the user program in SRAM when main power is off. Below approximately 3.0V, the CPU sets a BAT LED warning. Below 2.5V, you have an empty CPU. The critical detail: the battery drains faster when the CPU is powered on than when it is off. A 1785-L80B running continuously drains its battery in twelve to eighteen months — about half the life of the same battery in a powered-off spare. Replace the backup battery every twelve months, on a schedule. Write the replacement date inside the cabinet door with a paint marker. I have seen plants lose programs because the maintenance manager assumed the battery lasts five years. It does not in a warm panel running 24/7. Specific processor models to watch: · 1785-L80B — Full-featured processor with 256K memory. Highest battery drain due to larger SRAM array. Check BAT LED quarterly. · 1785-L40B — Mid-range processor, 128K memory. Slightly longer battery life than the L80B. When the program is lost, you need three things: the backup file (.RSP from RSLogix 5), the correct processor firmware, and a working connection to download.   1771 I/O Module Faults   The 1771-IBD uses optical isolators that degrade over time. After fifteen to twenty years, the current transfer ratio drifts. The input stops reliably detecting the OFF state — the CPU sees a logic 1 when the field device is de-energized. Replace the module when you see phantom ON states. 1771-OB (24V DC Sourcing Output) — The Darlington transistor arrays fail shorted or open. A shorted output keeps the load energized when the logic says OFF. The 1771-OB has no output fuse. Keep spares. 1771-IXE (Thermocouple/Millivolt Input) — Uses a custom hybrid ASIC that is no longer manufactured. When the ASIC fails, the module outputs random values or locks at a fixed reading. These are getting expensive on the secondary market because new-old-stock is exhausted.   RSLogix 5 Software Compatibility   RSLogix 5 is the only way to program and troubleshoot the PLC-5 family. Rockwell stopped selling new licenses years ago. Version 8.20 is the last release — a 32-bit application running on Windows 7 and Windows 10 in compatibility mode. Windows 11 is unreliable. Common RSLogix 5 issues in 2026: · DH+ communication via 1784-PCMK — The PCMCIA card is obsolete. Driver support ended with Windows 7. USB-to-DH+ converters (1784-U2DHP) cost $500-$1,200 and are themselves discontinued. · Serial DF1 upload — Requires a real RS-232 port. FTDI chipset-based USB adapters are the most reliable. Prolific-based adapters cause random corruption. · Ethernet upload (1785-L80C/L80E) — The most reliable method if your processor has Ethernet. Set a static IP, connect directly with a crossover cable, and use the Who Active feature. · Program file corruption — RSLogix 5 uses a serialization scheme. If an uploaded .RSP file will not download back to the CPU, create a new file and upload data tables first, then the program separately. Keep a dedicated laptop running Windows 7 or Windows 10 32-bit with RSLogix 5 installed. Do not let IT update it. Do not connect it to the internet.   Replacement Options: ControlLogix vs CompactLogix   You will eventually have to migrate. Here is the realistic breakdown.   ControlLogix Migration   The native replacement for PLC-5 is ControlLogix — the 1756-L8x series. Rockwell provides a migration toolkit that converts most ladder logic automatically. Simple discrete logic converts cleanly. PID loops, MSG instructions, and block transfers (BTR/BTW) require manual rework. Cost: a single ControlLogix chassis, processor, power supply, and communication module runs $5,000-$8,000 list. A full cabinet migration for a medium system (128 I/O points) runs $30,000-$60,000 in parts and engineering.   CompactLogix Migration   CompactLogix (5069-L3x or 5069-L4x series) is the lower-cost alternative at $2,000-$4,000 per processor. The 5069 I/O modules cost about 30% less than 1756 modules. Trade-offs: · CompactLogix supports fewer I/O points per chassis · No DH+ or Remote I/O built in — requires explicit communication modules · The 5069 backplane does not support 1771 adapter modules — all new I/O required For small to medium PLC-5 systems (under 128 I/O points), CompactLogix is the sensible choice. For large systems with significant analog I/O or existing ControlNet/RIO networks, the ControlLogix path saves integration headaches. The Reality of Migrations   Some vendors pitch a PAC migration as a drop-in replacement. It is not. The backplane, I/O, power supply, and programming environment all change. The only thing you keep is the field wiring. Budget for a complete system replacement.   Where to Find Spare Parts Today   New-old-stock PLC-5 and 1771 components are disappearing from traditional distribution. Rockwell does not manufacture them anymore. The remaining supply lives in the surplus and independent distributor network. Your best sourcing strategy: buy from an industrial automation spare parts specialist with tested inventory. At tztechio.com, the Allen-Bradley category carries curated PLC-5 processors, 1771 I/O modules, power supplies, and chassis — including 1785-L80B and 1785-L40B processors, 1771-IBD and 1771-OB I/O, and hard-to-find modules like the 1771-IXE thermocouple input. Broader PLC parts for other legacy platforms are also available.   What to Stockpile Now   If you maintain PLC-5 systems, supply tightens every quarter. Priority order: 1. 1771-PS7 power supply — Most common failure point. Stock two per active chassis. 2. 1785-L80B or L40B processor — One spare CPU per two systems. Buy tested units with verified battery backup circuitry. 3. 1770-XY batteries — Buy a case of twelve. Change every twelve months across all systems. 4. 1771-IBD and 1771-OB — Two of each per system. Highest failure rate among I/O modules. 5. 1771-IXE or other analog input modules — One spare per module type. Hardest to find. 6. 1771 chassis — One spare backplane per system size. A cracked chassis means full rewiring. 7. RSLogix 5 installation media and license — If you do not have it, find a licensed copy now. When your programming laptop dies, you will not be able to set up a new one.   What This Means for Your Plant   The PLC-5 is not coming back. Rockwell will not re-release it. Every day makes spare parts harder to find and more expensive. The plant manager who says "we will migrate next year" has been saying that for five years. The refrigeration skid CPU I replaced at 11 PM that Tuesday night was the same one the plant planned to migrate in 2019. Keep spares. Change batteries. Maintain your RSLogix 5 laptop. And when the budget appears for a migration, do it before the PLC-5 fails — not after. A controlled migration beats an emergency replacement every time. ------------------------------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).
  • Fuji Electric MICREX PLC: Migration Options for End-of-Life Systems
    Fuji Electric MICREX PLC: Migration Options for End-of-Life Systems Jul 14, 2026
      Fuji Electric has been a dominant force in industrial automation across Japan and Southeast Asia for decades, with its MICREX PLC family installed in thousands of factories handling food processing, material handling, and water treatment. But the landscape has shifted. Fuji Electric has consolidated its programmable controller lineup around the SPH5000 and SPH3000M platforms, and the older generations — the MICREX-SX SPH200/300/500 series, the MICREX-NX family, and early SPH1000 systems — have all reached or are approaching end-of-life. If you are maintaining a line built around one of these legacy controllers, you face a familiar industrial dilemma: keep sourcing replacement parts on the used market, or commit to a migration project. Neither path is risk-free. The right answer depends on your specific hardware revision, I/O count, tolerance for downtime, and long-term production plan. Here are the five questions that come up most often when engineers realize their Fuji MICREX system is no longer fully supported. The answers are model-specific and grounded in what's actually available in 2026.   1. Which Fuji Electric MICREX Models Are Obsolete?   Fuji Electric has published formal end-of-life notices for several MICREX families. Here is the current status as of mid-2026: MICREX-SX SPH200 Series (Discontinued — No Factory Support) The SPH200 was Fuji's entry-level modular PLC in the MICREX-SX lineup. CPU models like the NP1FH-200 and NP1PH-200 were discontinued more than a decade ago. Fuji stopped accepting repair orders for these CPUs in 2019. If you have an SPH200 on your line, you are already running on whatever spare stock exists in the channel. MICREX-SX SPH300 Series (Discontinued — Support Ended) The SPH300 (CPU models NP1FH-300, NP1PH-300, NP1PS-300) was the mid-range workhorse of the MICREX-SX family. Formally discontinued in 2020, the five-year post-discontinuation support window has now closed in all regions. In Japan and parts of SE Asia, depot repair for emergency cases may still be available through authorized distributors with old stock of spare CPU boards, but wait times have stretched from weeks to months. MICREX-NX Series (Obsolete — No Support) The MICREX-NX family predates the MICREX-SX line and uses a completely different backplane and I/O form factor. Models like the NX-32, NX-64, and NX-128 CPU units have been out of production since the early 2000s. Spare parts are only available through third-party brokers or surplus dealers. MICREX-SX SPH500 Series (End-of-Life Active) The SPH500 (CPU models NP1PH-500, NP1PS-500) shares the same backplane form factor as the SPH1000 and SPH3000M, but Fuji is phasing it out in favor of the SPH5000M. Factory support is expected to end completely by 2028. Fuji still manufactures replacement CPU modules for warranty contracts, but new-unit pricing has increased 30-40% since 2023 as production volumes dropped. MICREX-SX SPH1000 Series (Support Phasedown) The SPH1000 (CPU models NP1PS-1000, NP1PH-1000) bridges the gap between old MICREX-SX and the current SPH5000 architecture. Fuji still sells these CPUs, but lead times for factory orders have stretched to 12-16 weeks. Fuji recommends the SPH5000M as the direct replacement for new projects. Key takeaway: If your CPU is an SPH200 or SPH300, you are past the point of factory support. SPH500 and SPH1000 users have a narrowing migration window — roughly 12 to 24 months depending on your region. --- 2. Can I Replace a MICREX-SX with an SPH Directly?   This is the single most common question from engineers managing Fuji lines. Short answer: it depends on the CPU generation. Physical Compatibility — I/O Modules The good news: Fuji Electric maintained the same backplane form factor across the SPH200, SPH300, SPH500, SPH1000, SPH3000M, and SPH5000M families. Your existing I/O modules — digital input modules like NP1X32-DC24, analog modules like NP1A04-AD, and specialty modules like NP1CN1 (T-LINK), NP1CN2 (FL-net), and NP1CN3 (PROFIBUS) — can be taken out of the old rack and plugged directly into a new SPH5000M rack. The I/O bus protocol is electrically compatible across these generations, making a CPU-only swap physically possible. CPU and Firmware — Not a Direct Swap The catch is the CPU module and programming environment. An SPH5000M CPU (model NP1PS-5000M or NP1PH-5000M) will not run SX-Programmer project files compiled for an SPH200 or SPH300 without significant rework. The instruction set expanded between generations. Memory maps for T-LINK and FL-net communication areas changed. Interrupt handling and task scheduling that worked on the SPH300 may behave differently on the SPH5000M. What this means in practice: you can keep your field wiring, I/O rack, power supplies, and base modules. You will need to rewrite the application logic in Standard SX-Programmer or the newer NP (Nano Programming) environment and revalidate it. Practical Drop-In Path The most straightforward migration path is SPH1000 → SPH5000M. If you have an SPH1000 running Standard SX-Programmer projects compiled under V6.x or later, the conversion involves recompiling the project, checking communication configuration, and swapping the CPU module. For SPH200/300 users on older SX-Programmer V3.x/V4.x projects, expect a full program rewrite. --- 3. What Programming Software Works with Legacy vs. New Fuji PLCs?   Software compatibility is often the make-or-break factor in any MICREX migration. Using the wrong software version can corrupt project files or fail to communicate with the CPU entirely. SX-Programmer (Legacy — SPH200/300/500) The original SX-Programmer, typically V3.x through V5.x, is the only software that can compile and download logic to SPH200 and SPH300 CPUs. It runs on Windows XP through Windows 7 (32-bit). It does not install correctly on Windows 10 or 11 without a virtual machine. Communication uses the SX bus protocol over RS-232C or USB-to-serial adapters with the NP1W-CN1 cable. If you need to maintain an SPH200 or SPH300 line, keep a dedicated Windows 7 PC with SX-Programmer V5.2 or later. Standard SX-Programmer (Transition — SPH1000/SPH3000M) Standard SX-Programmer V6.x and V7.x supports the SPH1000, SPH3000M, and early SPH5000M firmware revisions. It runs on Windows 7 and Windows 10 (64-bit) and uses a different project file format (.sxp vs. the older .sxc). Projects created in V3.x/V4.x must be manually re-created — there is no automatic conversion utility. This version also introduced device configuration files for EtherNet/IP and PROFINET modules. If your legacy system used T-LINK or FL-net, expect to reconfigure communication parameters from scratch. NP (Nano Programming) Software (Current — SPH5000M) Fuji Electric's current programming environment, NP software, supports the SPH5000M and SPH3000M with the latest firmware. It runs on Windows 10 and Windows 11 (64-bit) and provides structured text (ST), ladder diagram (LD), and function block diagram (FBD) editors. NP software does not support SPH200, SPH300, or SPH500 CPUs at all — connecting to these older CPUs will fail at the communication handshake. NP projects are not backward-compatible with Standard SX-Programmer. Legacy CPU | Required Software | Migration Path SPH200/300 | SX-Programmer V3-V5 | Full rewrite in Standard SX-Programmer or NP SPH500 | SX-Programmer V5+ | Standard SX-Programmer V6/V7 → export to NP SPH1000 | Standard SX-Programmer V6/V7 | Recompile in NP + revalidate SPH5000M | NP software (current) | Current platform — no migration needed --- 4. What's the Cost of Migrating vs. Sourcing Used Parts?   Cost is where the numbers get real — and rarely as clean as the vendor brochures suggest. Sourcing Used Parts — The Short-Term Path A used SPH300 CPU (NP1PH-300) on the surplus market ranges from $150 to $400 depending on condition and revision. A used SPH500 CPU runs $350 to $700. I/O modules are cheaper: $30 to $80 for digital inputs, $80 to $200 for analog modules. The math looks attractive for a single CPU swap. The risk is buying a component with unknown runtime hours, stored in uncontrolled conditions, with no warranty beyond "tested on power-up." We have seen buyers receive CPUs with corroded battery contacts, expired firmware revisions, or modules that passed a bench test but failed after three weeks of production vibration. If your line runs 24/7 and downtime costs $5,000+ per hour, one unexpected failure of a used CPU wipes out any apparent savings. Migration — The Long-Term Path A full migration from an SPH300 to an SPH5000M typically costs $8,000 to $18,000 per cabinet in hardware (CPU, memory card, power supply, communication modules). Labor for programming, panel rework, and commissioning adds $5,000 to $12,000 per cabinet depending on program complexity. For a 256-I/O-point food processing skid running an SPH500, budget $15,000 to $20,000 for a full migration. For a 512-point water treatment line with multiple SPH300 CPUs on T-LINK, expect $25,000 to $40,000. The Breakeven Calculation The breakeven point comes when you have replaced a critical CPU more than once. Buy a used SPH300 for $350, it runs 14 months, fails, and you buy another for $400 plus $150 emergency shipping — you are at $900 with no guarantee the third unit lasts longer. At that point, the migration cost looks like an investment in reliability. For plants running MICREX-NX systems, used parts are the only option since Fuji no longer manufactures compatible components. Migration requires replacing the entire backplane and I/O infrastructure, pushing costs to $30,000+ per cabinet. Regional Factors In Japan and SE Asia, used Fuji MICREX parts are 15-25% cheaper than in North America or Europe, reflecting the larger installed base. In the Middle East — particularly UAE, Saudi Arabia, and Qatar food processing plants — Fuji spare parts command a 30-40% premium because most must be imported from Japan or Singapore with 4-6 week lead times. --- 5. Where Can I Find Spare Parts for Legacy MICREX Systems?   When factory support runs out, the secondary market becomes essential. Here is where engineers actually source Fuji MICREX spare parts in 2026. Specialized Automation Parts Suppliers For a broad inventory of Fuji MICREX CPUs, I/O modules, power supplies, and communication modules, your best source is a dedicated industrial automation parts supplier like TZ Techio, which stocks new-old-stock and tested used components across the SPH200, SPH300, SPH500, SPH1000, and SPH3000M families. These suppliers typically test each module before listing and offer a 30-day warranty. Japanese Surplus Brokers Companies like Nippon Avionics and Marubun, along with regional surplus houses in Osaka and Nagoya, are primary clearinghouses for decommissioned Fuji equipment. Pricing is competitive if you buy direct, but requires Japanese-language capability and a freight forwarder. Expect minimum order quantities of 3-5 units for CPUs. Auction Platforms Yahoo! Japan Auctions and Mercari Japan are the deepest markets for used Fuji MICREX parts, but they require a proxy buying service (Buyee, FromJapan). We estimate 60-70% of all used Fuji PLC parts change hands through Japanese domestic channels before appearing in international listings. By the time a module hits eBay or Alibaba, it has typically been marked up 50-100%. What to Stockpile If you plan to keep a legacy MICREX system running another 3-5 years, prioritize: 1. CPU module — the most failure-prone and hardest to source over time 2. Battery backup module (CR123A-based) — ages on the shelf and fails silently 3. Communication modules (T-LINK NP1CN1, FL-net NP1CN2) — no substitutes available 4. Power supply module — electrolytic capacitors age regardless of runtime --- Decision Guide: Migrate or Source Spare Parts?   Use this table to evaluate your specific situation. No single answer fits every plant. Factor | Migrate to SPH5000M | Source Used Parts Current CPU | SPH500 or newer | SPH200/300 or MICREX-NX I/O count | 128+ points | Under 128 points Line criticality | 24/7 uptime required | Non-critical or backup line Support window | Need warranty, factory support | Can tolerate unplanned downtime Budget horizon | 5+ year ROI on reliability | 12-18 month horizon Geography | North America, Europe, Middle East | Japan, SE Asia (good parts availability) Software status | Have Standard SX-Programmer V6+ | Running legacy SX-Programmer V3-V5 Spare CPU cost | N/A (new) | Under $300 each Risk tolerance | Low — cannot absorb random failure | High — can swap and recover For plants running SPH200 or SPH300 CPUs with fewer than 128 I/O points on non-critical lines, sourcing used parts is defensible for the next 18-24 months. Stockpile two spare CPUs, a handful of I/O modules, and backup batteries. Monitor the surplus market quarterly — SPH300 CPU prices have been climbing 8-12% per year as supply contracts. For every other scenario — particularly SPH500 or SPH1000 users in North America, the Middle East, or Europe — the migration math favors the SPH5000M. The window for an orderly, planned migration is narrowing. If you need to locate specific Fuji MICREX spare parts or compare pricing on new-old-stock modules, browse the PLC category at TZ Techio or explore the broader industrial automation inventory. A reliable supply chain for legacy hardware — or a clear migration path to current platforms — is the difference between a scheduled upgrade and an emergency shutdown. ----------------------------------------------------------------------------------------------------------------- 🏢 About TZ Tech   TZ Tech is a leading supplier of industrial automation, electrical, instrumentation, and telecommunications components. We specialize in sourcing ready-to-ship distributor stock, allowing us to offer highly competitive pricing and short lead times. Thanks to our extensive inventory, we can even source rare and discontinued parts that are hard to find elsewhere.   🛡️ Our Quality Commitment   We understand that quality is your top priority. Every component undergoes a strict screening and inspection process so you can buy with absolute confidence. For legacy or discontinued parts, we believe in complete transparency and will always provide an honest, accurate report on the product's condition. Plus, all brand-new parts come backed by a full 1-year warranty.   ✉️ Get in Touch     Have a project or a part you need? Send us your inquiry today! Our team is dedicated to providing a fast response within 6 hours (excluding weekends).
1 2 3 4 5
A total of5pages
Subscribe

Please read on, stay posted, subscribe, and we welcome you to tell us what you think.

submit
Copyright 2026 @ TZ TECH Co., LTD. .All Rights Reserved Disclaimer: We are not an authorized distributor or distributor of the product manufacturer of this website, The product may have older date codes or be an older series than that available direct from the factory or authorized dealers. Because our company is not an authorized distributor of this product, the Original Manufacturer’s warranty does not apply.While many DCS PLC products will have firmware already installed, Our company makes no representation as to whether a DSC PLC product will or will not have firmware and, if it does have firmware, whether the firmware is the revision level that you need for your application. Our company also makes no representations as to your ability or right to download or otherwise obtain firmware for the product from our company, its distributors, or any other source. Our company also makes no representations as to your right to install any such firmware on the product. Our company will not obtain or supply firmware on your behalf. It is your obligation to comply with the terms of any End-User License Agreement or similar document related to obtaining or installing firmware.

Sitemap | Blog | XML | Privacy Policy

leave a message

leave a message
If you are interested in our products and want to know more details,please leave a message here,we will reply you as soon as we can.
submit

Home

Products

whatsApp

contact

YOUR COOKIE SETTINGS

In addition, with your permission, we want to place cookies to make your visit anointeraction with slOC more personal. For this we use analytical and advertisingcookies. With these cookies we and third parties can track and collect yourinternet behawior inside and outside super-instrument.com. With this we and third parties adapt super-instrument.com and advertisementsto your interest. By clicking Accept you agree to this. If you decline, we only usethe necessary cookies and you unfortunately will not receive any personalizedcontent. Please visit our Cookie policy for more information or to change yourconsent in the future.

Accept and continue Decline cookies